

[2023年11月] 最新のMicrosoft DP-300認定練習テスト問題
確認済みDP-300問題集と解答で一年間無料最速更新
Microsoft DP-300は、Microsoft Azureでリレーショナルデータベースを管理する専門家のスキルと知識をテストする試験です。この試験は、Azure SQLデータベースを扱うデータベース管理者、開発者、およびデータの専門家向けに設計されています。 DP-300試験は、Azure SQLデータベースを管理および維持するために必要なスキルを検証するMicrosoft Certified:Azure Database Administrator Associate認定の一部です。
質問 # 124
HOTSPOT
You have an Azure Synapse Analytics dedicated SQL pool named Pool1 and an Azure Data Lake Storage Gen2 account named Account1.
You plan to access the files in Account1 by using an external table.
You need to create a data source in Pool1 that you can reference when you create the external table.
How should you complete the Transact-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Hot Area:
正解:
解説:
Section: [none]
Explanation:
Box 1: blob
The following example creates an external data source for Azure Data Lake Gen2 CREATE EXTERNAL DATA SOURCE YellowTaxi WITH ( LOCATION = 'https://azureopendatastorage.blob.core.windows.net/nyctlc/yellow/', TYPE = HADOOP) Box 2: HADOOP Reference:
https://docs.microsoft.com/en-us/azure/synapse-analytics/sql/develop-tables-external-tables
質問 # 125
You are building a database backup solution for a SQL Server database hosted on an Azure virtual machine.
In the event of an Azure regional outage, you need to be able to restore the database backups. The solution
must minimize costs.
Which type of storage accounts should you use for the backups?
- A. read-access geo-redundant storage (RA-GRS)
- B. zone-redundant storage (ZRS)
- C. geo-redundant storage
- D. locally-redundant storage (LRS)
正解:A
解説:
Section: [none]
Explanation:
Geo-redundant storage (with GRS or GZRS) replicates your data to another physical location in the secondary
region to protect against regional outages. However, that data is available to be read only if the customer or
Microsoft initiates a failover from the primary to secondary region. When you enable read access to the
secondary region, your data is available to be read if the primary region becomes unavailable. For read access
to the secondary region, enable read-access geo-redundant storage (RA-GRS) or read-access geo-zone-
redundant storage (RA-GZRS).
Incorrect Answers:
A: Locally redundant storage (LRS) copies your data synchronously three times within a single physical location
in the primary region. LRS is the least expensive replication option, but is not recommended for applications
requiring high availability.
C: Zone-redundant storage (ZRS) copies your data synchronously across three Azure availability zones in the
primary region.
D: Geo-redundant storage (with GRS or GZRS) replicates your data to another physical location in the
secondary region to protect against regional outages. However, that data is available to be read only if the
customer or Microsoft initiates a failover from the primary to secondary region.
Reference:
https://docs.microsoft.com/en-us/azure/storage/common/storage-redundancy
質問 # 126
You have an Azure subscription that is linked to a hybrid Azure Active Directory (Azure AD) tenant. The subscription contains an Azure Synapse Analytics SQL pool named Pool1.
You need to recommend an authentication solution for Pool1. The solution must support multi-factor authentication (MFA) and database-level authentication.
Which authentication solution or solutions should you include in the recommendation? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.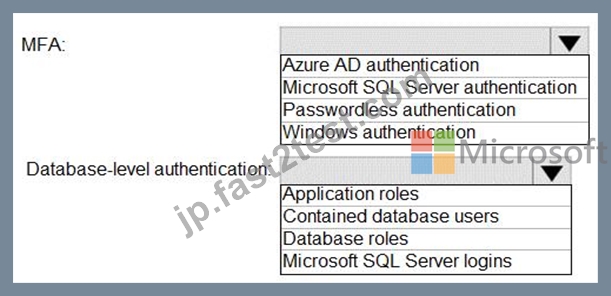
正解:
解説: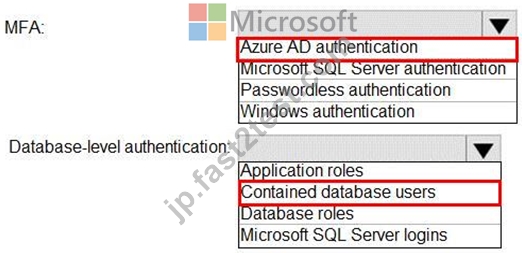
Reference:
https://docs.microsoft.com/en-us/azure/synapse-analytics/sql-data-warehouse/sql-data-warehouse-authentication
質問 # 127
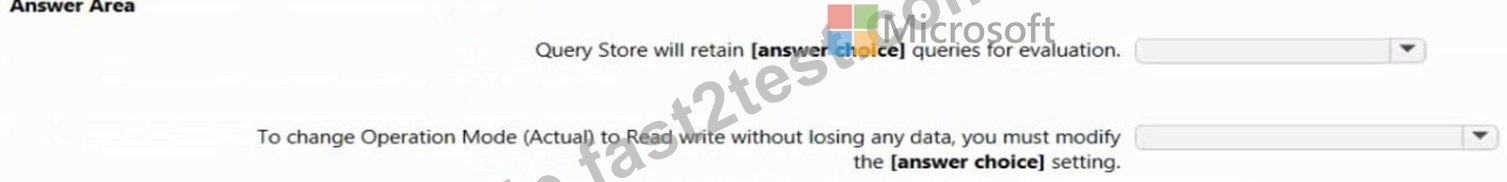
You have a database on a SQL Server on Azure Virtual Machines instance.
The current state of Query Store for the database is shown in the following exhibit.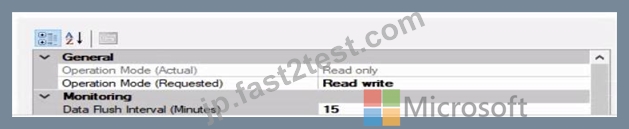
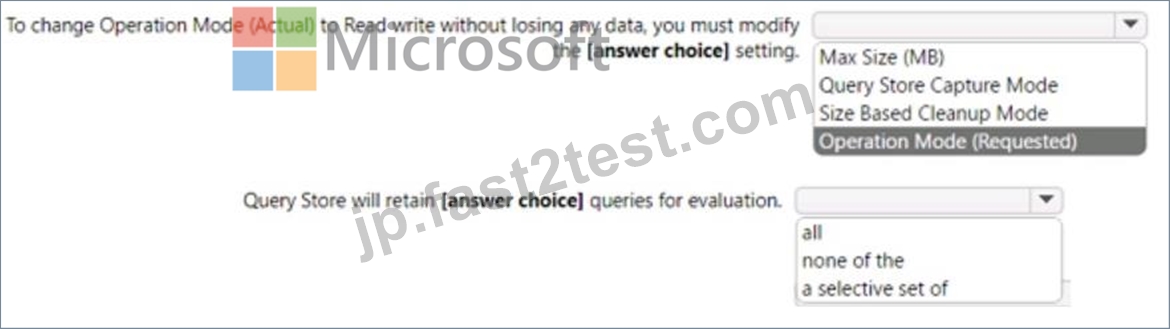
正解:
解説: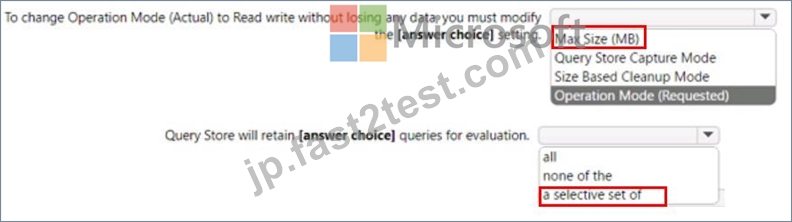
質問 # 128
You have an Azure SQL database.
You have a query and the associated execution plan as shown in the following exhibit.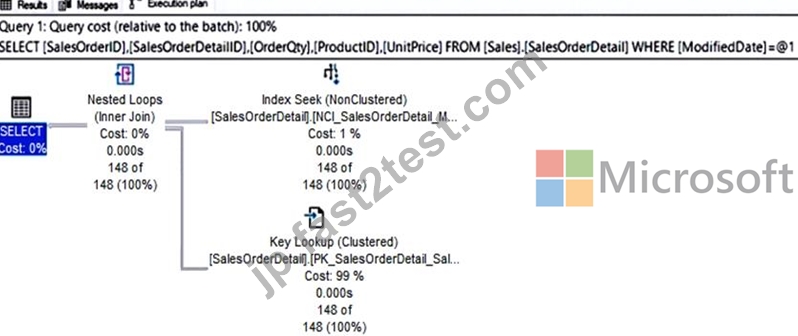
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.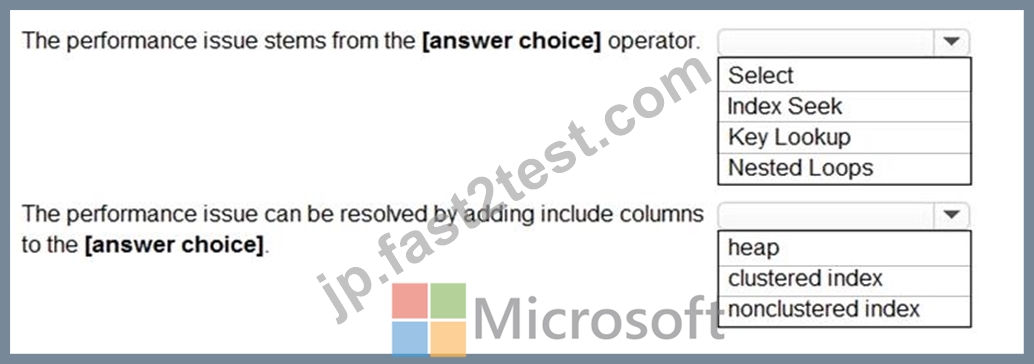
正解:
解説: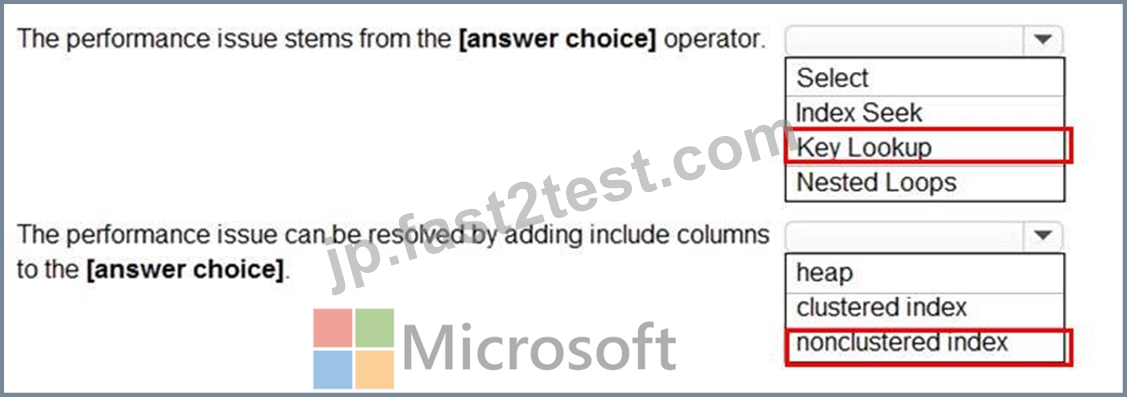
質問 # 129
You plan to create a table in an Azure Synapse Analytics dedicated SQL pool.
Data in the table will be retained for five years. Once a year, data that is older than five years will be deleted.
You need to ensure that the data is distributed evenly across partitions. The solutions must minimize the amount of time required to delete old data.
How should you complete the Transact-SQL statement? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all.
You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.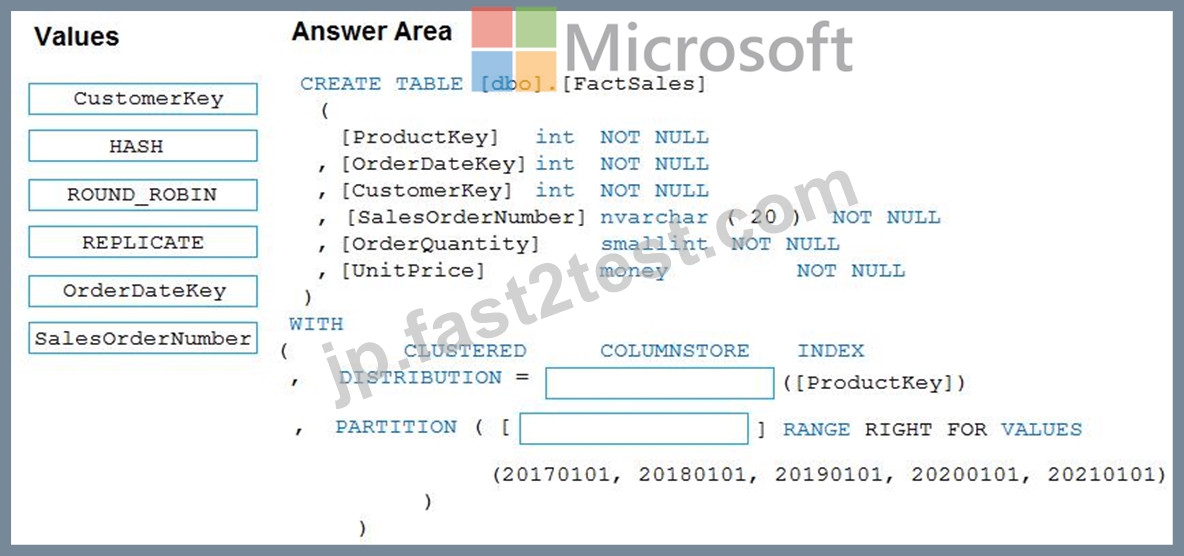
正解:
解説: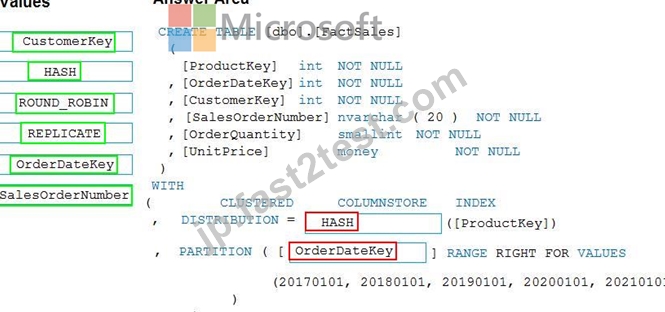
Reference:
https://docs.microsoft.com/en-us/sql/t-sql/statements/create-table-azure-sql-data-warehouse
https://docs.microsoft.com/en-us/azure/synapse-analytics/sql/best-practices-dedicated-sql-pool
質問 # 130
You have an Azure Data Factory that contains 10 pipelines.
You need to label each pipeline with its main purpose of either ingest, transform, or load. The labels must be available for grouping and filtering when using the monitoring experience in Data Factory.
What should you add to each pipeline?
- A. a resource tag
- B. a user property
- C. a correlation ID
- D. a run group ID
- E. an annotation
正解:E
解説:
Section: [none]
Explanation:
Azure Data Factory annotations help you easily filter different Azure Data Factory objects based on a tag. You can define tags so you can see their performance or find errors faster.
Reference:
https://www.techtalkcorner.com/monitor-azure-data-factory-annotations/
質問 # 131
You need to design an analytical storage solution for the transactional dat a. The solution must meet the sales transaction dataset requirements.
What should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.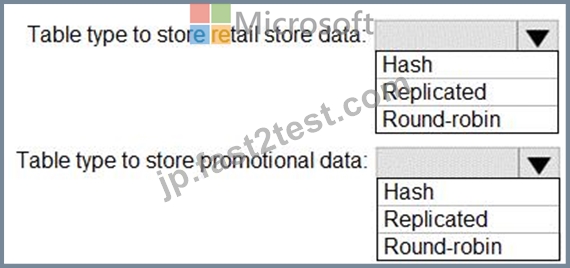
正解:
解説: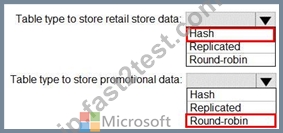
Reference:
https://rajanieshkaushikk.com/2020/09/09/how-to-choose-right-data-distribution-strategy-for-azure-synapse/
質問 # 132
You need to trigger an Azure Data Factory pipeline when a file arrives in an Azure Data Lake Storage Gen2 container.
Which resource provider should you enable?
- A. Microsoft.EventGrid
- B. Microsoft.EventHub
- C. Microsoft.Automation
- D. Microsoft.Sql
正解:A
解説:
Event-driven architecture (EDA) is a common data integration pattern that involves production, detection, consumption, and reaction to events. Data integration scenarios often require Data Factory customers to trigger
pipelines based on events happening in storage account, such as the arrival or deletion of a file in Azure Blob Storage account. Data Factory natively integrates with Azure Event Grid, which lets you trigger pipelines on such events.
Reference:
https://docs.microsoft.com/en-us/azure/data-factory/how-to-create-event-trigger
質問 # 133
You are provisioning an Azure SQL database in the Azure portal as shown in the following exhibit.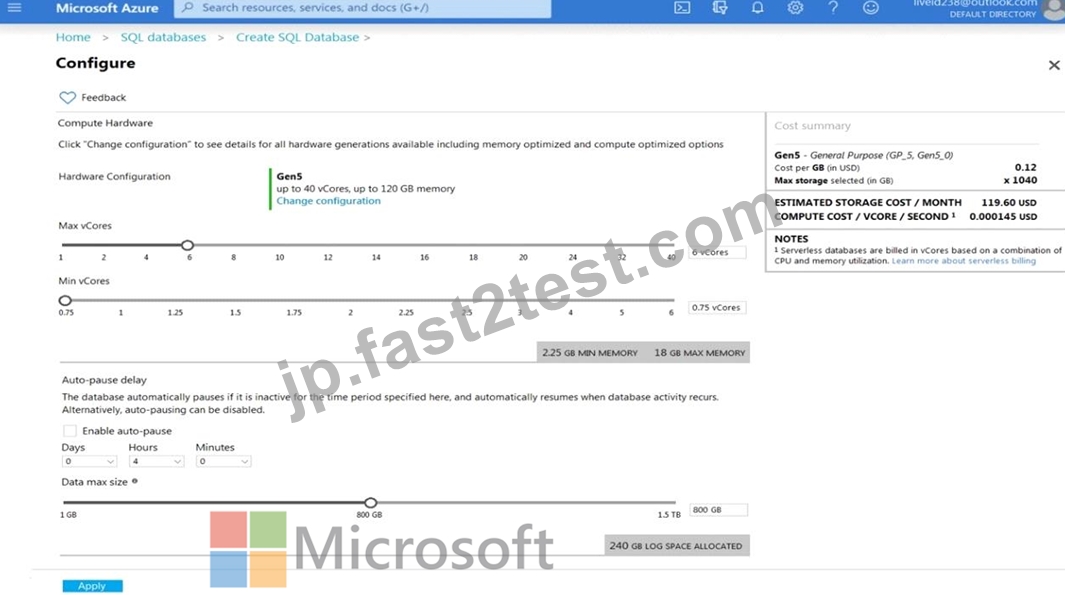
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.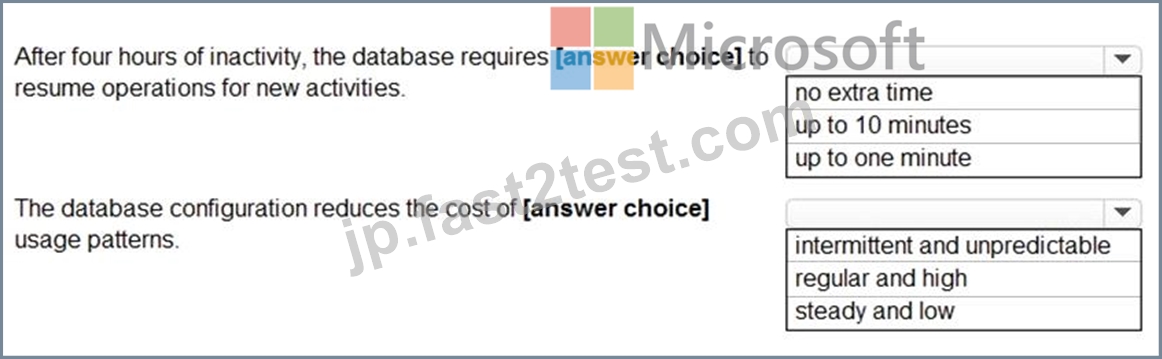
正解:
解説: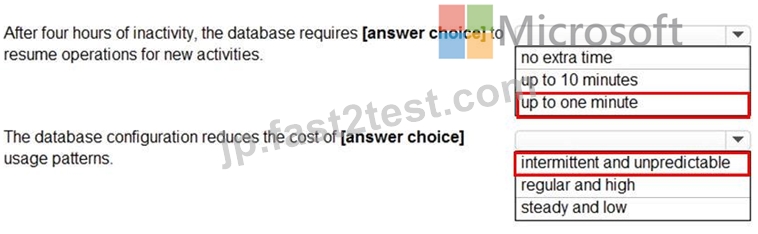
Reference:
https://docs.microsoft.com/en-us/azure/azure-sql/database/serverless-tier-overview
質問 # 134
You have a SQL Server on Azure Virtual Machines instance named VM1 that hosts a database named DB1. You run the following query.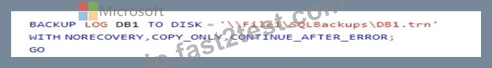
For each of the following statements, select Yes if the statement is true. Otherwise, select No.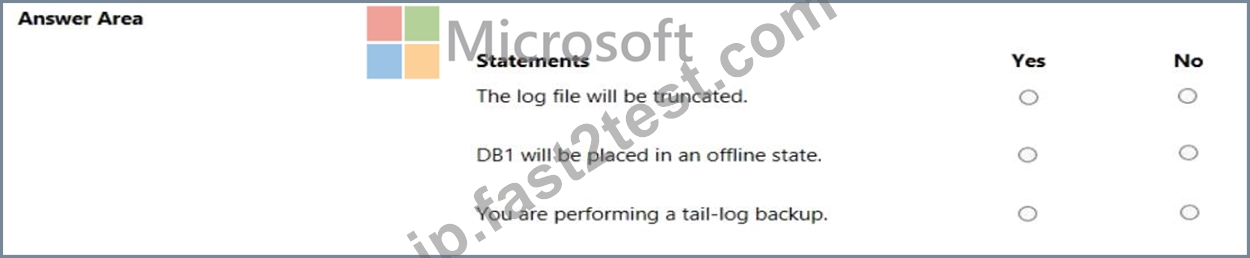
正解:
解説: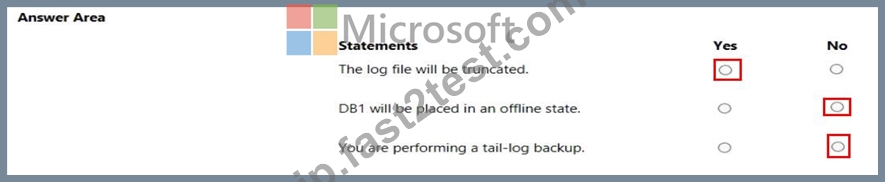
質問 # 135
You are performing exploratory analysis of bus fare data in an Azure Data Lake Storage Gen2 account by using an Azure Synapse Analytics serverless SQL pool.
You execute the Transact-SQL query shown in the following exhibit.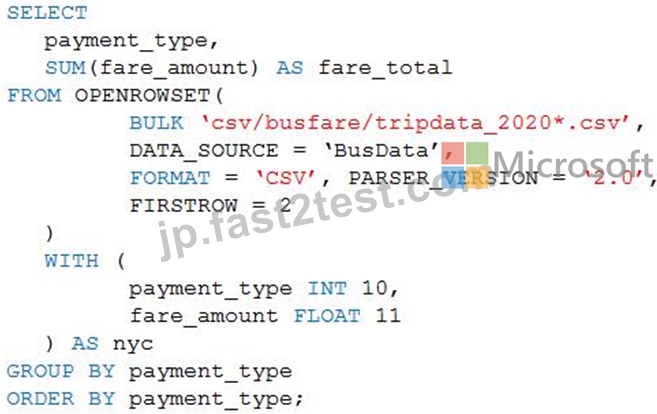
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic.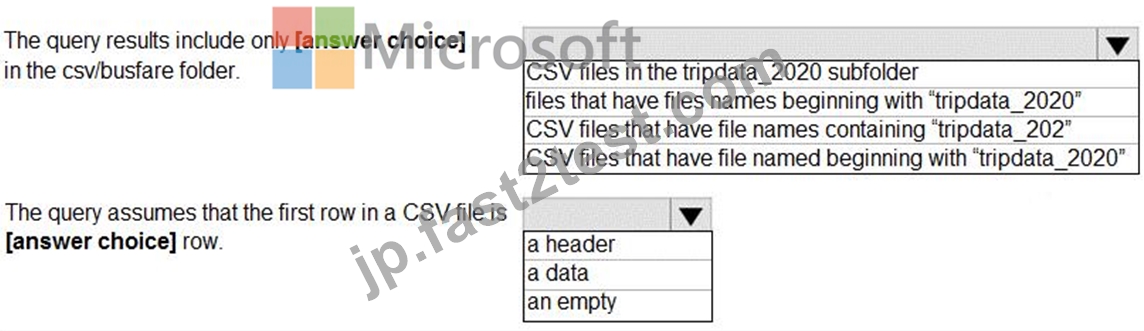
正解:
解説: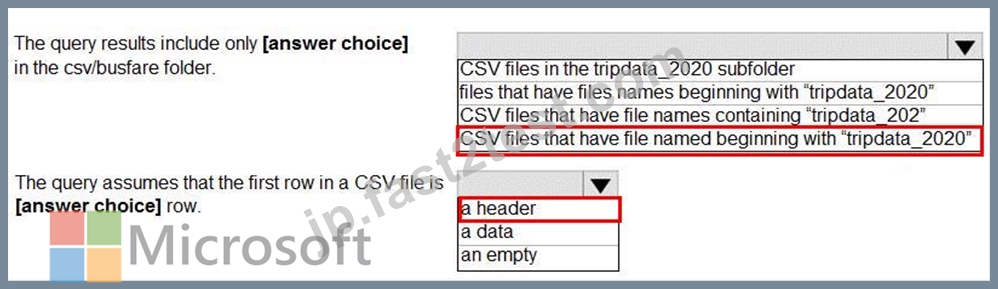
Reference:
https://docs.microsoft.com/en-us/azure/synapse-analytics/sql/develop-openrowset
質問 # 136
You are building an Azure Stream Analytics job to retrieve game data.
You need to ensure that the job returns the highest scoring record for each five-minute time interval of each game.
How should you complete the Stream Analytics query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.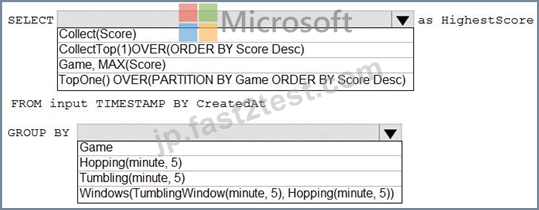
正解:
解説: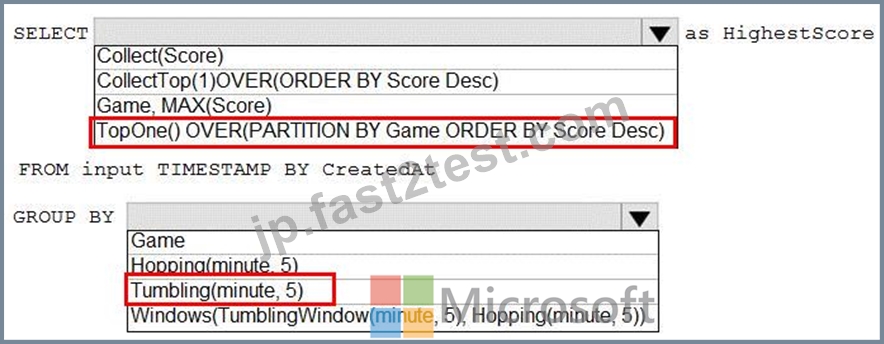
Reference:
https://docs.microsoft.com/en-us/stream-analytics-query/topone-azure-stream-analytics
https://github.com/MicrosoftDocs/azure-docs/blob/master/articles/stream-analytics/stream-analytics-window-functions.md
質問 # 137
You have an Azure SQL database named db1 that contains an Azure Active Directory (Azure AD) user named user1.
You need to test impersonation of user1 in db1 by running a SELECT statement and returning to the original execution context.
How should you complete the Transact-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.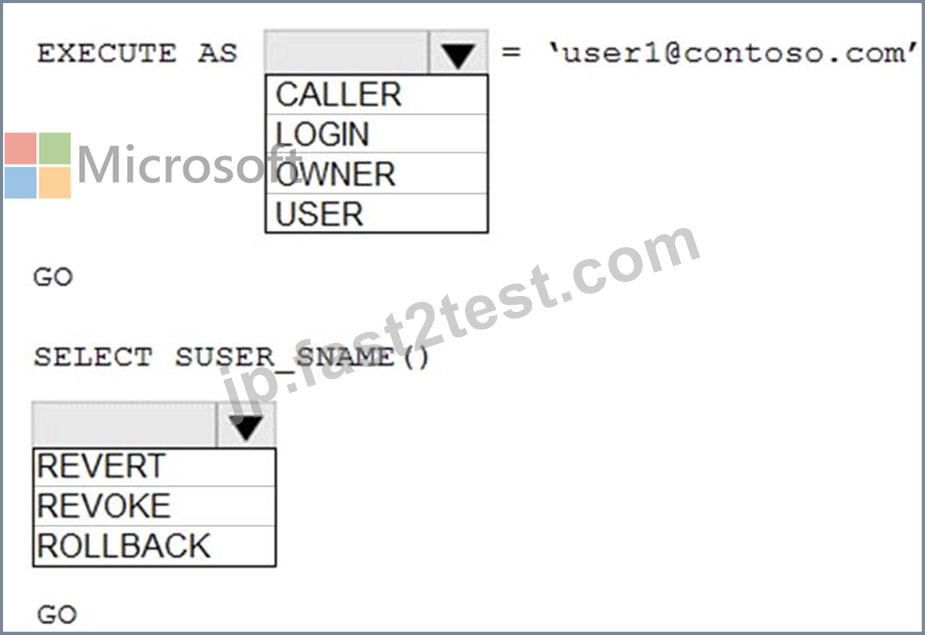
正解:
解説: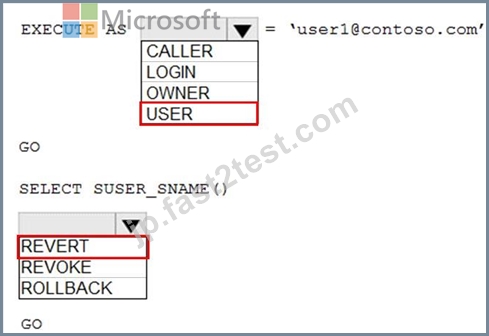
Reference:
https://docs.microsoft.com/en-us/sql/t-sql/statements/execute-as-transact-sql?view=sql-server-ver15
https://docs.microsoft.com/en-us/sql/t-sql/functions/suser-sname-transact-sql?view=sql-server-ver15
質問 # 138
You have an Azure SQL database named DB1 that contains two tables named Table1 and Table2. Both tables contain a column named a Column1. Column1 is used for joins by an application named App1.
You need to protect the contents of Column1 at rest, in transit, and in use.
How should you protect the contents of Column1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
正解:
解説: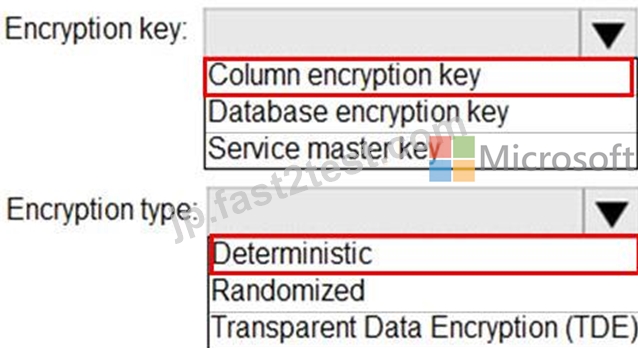
Reference:
https://docs.microsoft.com/en-us/sql/relational-databases/security/encryption/always-encrypted-database-engine
質問 # 139
You have an Azure SQL database.
You are reviewing a slow performing query as shown in the following exhibit.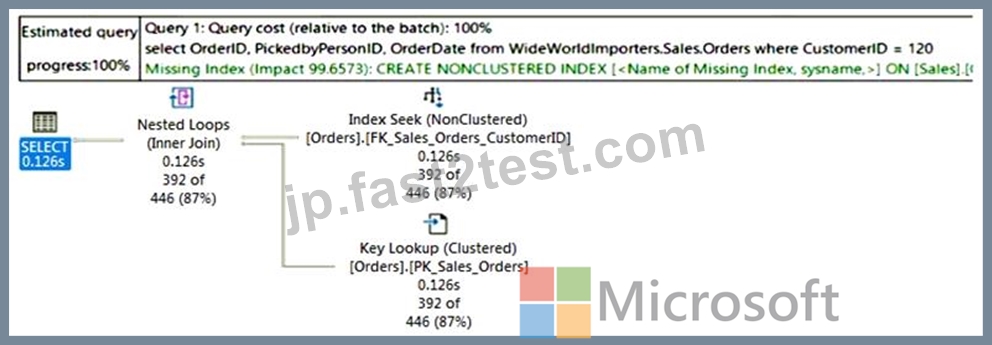
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.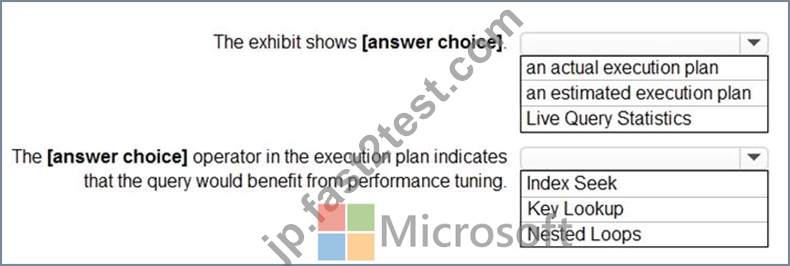
正解:
解説: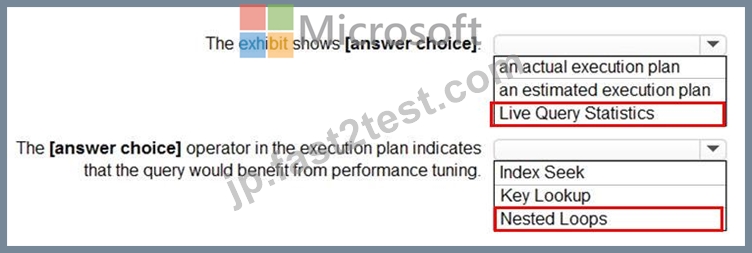
Reference:
https://docs.microsoft.com/en-us/sql/relational-databases/performance/live-query-statistics?view=sql-server-ver15
質問 # 140
You are building a database in an Azure Synapse Analytics serverless SQL pool.
You have data stored in Parquet files in an Azure Data Lake Storage Gen2 container.
Records are structured as shown in the following sample.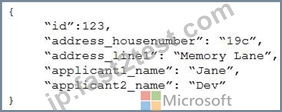
The records contain two applicants at most.
You need to build a table that includes only the address fields.
How should you complete the Transact-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.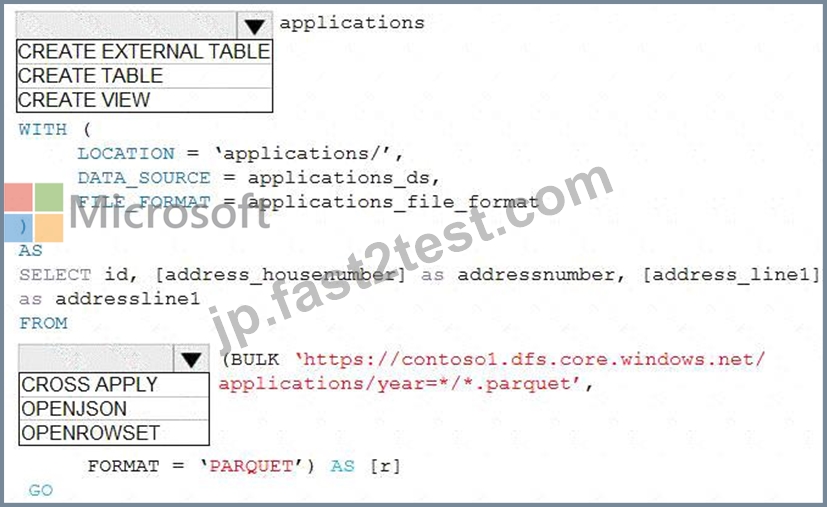
正解:
解説: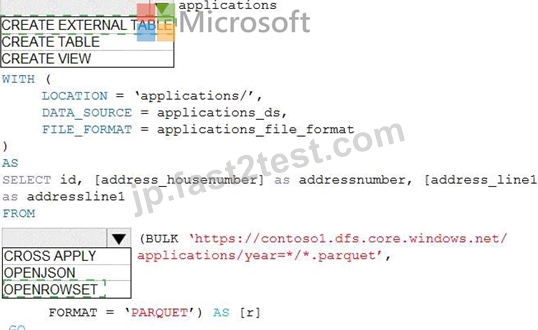
Explanation
Graphical user interface, text, application Description automatically generated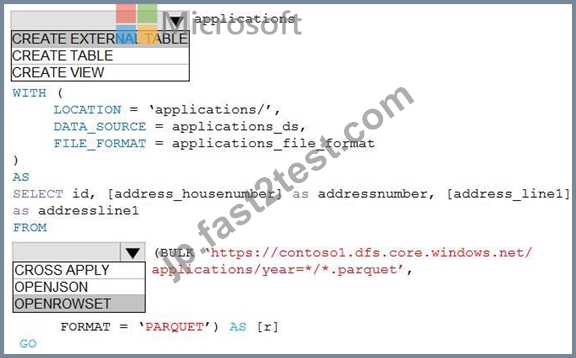
Box 1: CREATE EXTERNAL TABLE
An external table points to data located in Hadoop, Azure Storage blob, or Azure Data Lake Storage. External tables are used to read data from files or write data to files in Azure Storage. With Synapse SQL, you can use external tables to read external data using dedicated SQL pool or serverless SQL pool.
Syntax:
CREATE EXTERNAL TABLE { database_name.schema_name.table_name | schema_name.table_name | table_name } ( <column_definition> [ ,...n ] ) WITH ( LOCATION = 'folder_or_filepath', DATA_SOURCE = external_data_source_name, FILE_FORMAT = external_file_format_name Box 2. OPENROWSET When using serverless SQL pool, CETAS is used to create an external table and export query results to Azure Storage Blob or Azure Data Lake Storage Gen2.
Example:
AS
SELECT decennialTime, stateName, SUM(population) AS population
FROM
OPENROWSET(BULK
'https://azureopendatastorage.blob.core.windows.net/censusdatacontainer/release/us_population_county/year=*/* FORMAT='PARQUET') AS [r] GROUP BY decennialTime, stateName GO Reference:
https://docs.microsoft.com/en-us/azure/synapse-analytics/sql/develop-tables-external-tables
質問 # 141
You have SQL Server on an Azure virtual machine.
You review the query plan shown in the following exhibit.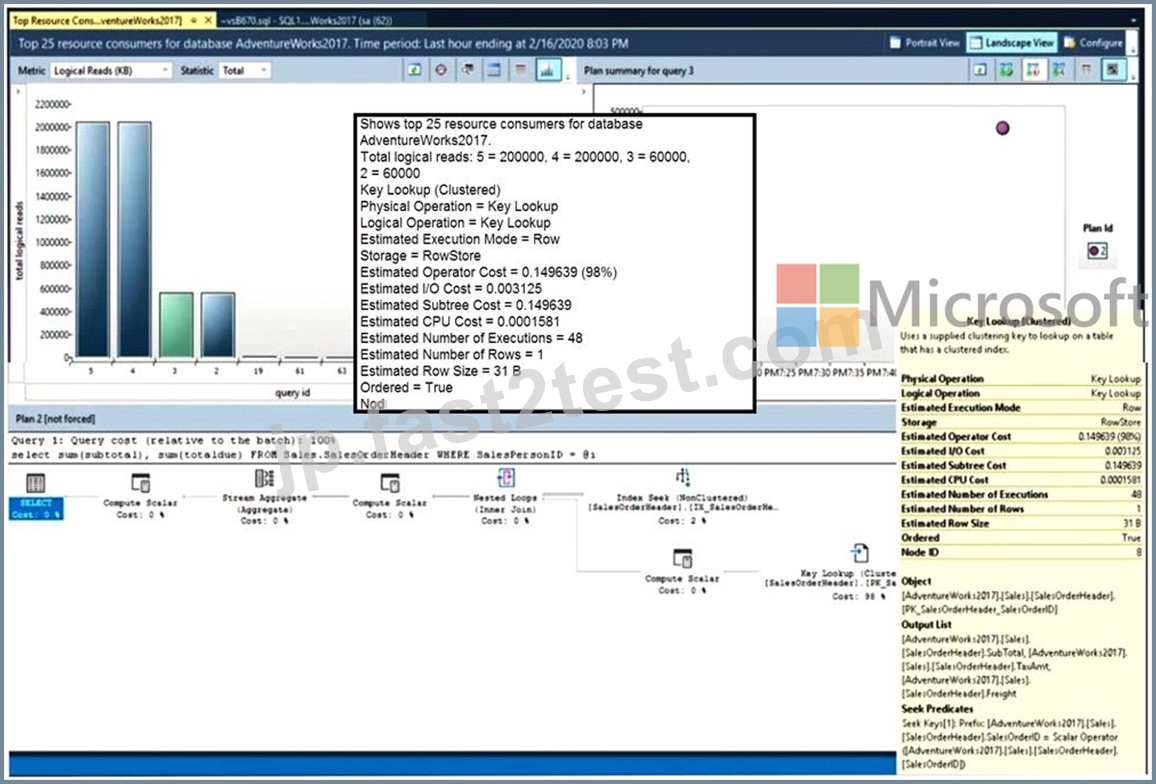
For each of the following statements, select yes if the statement is true. Otherwise, select no.
NOTE: Each correct selection is worth one point.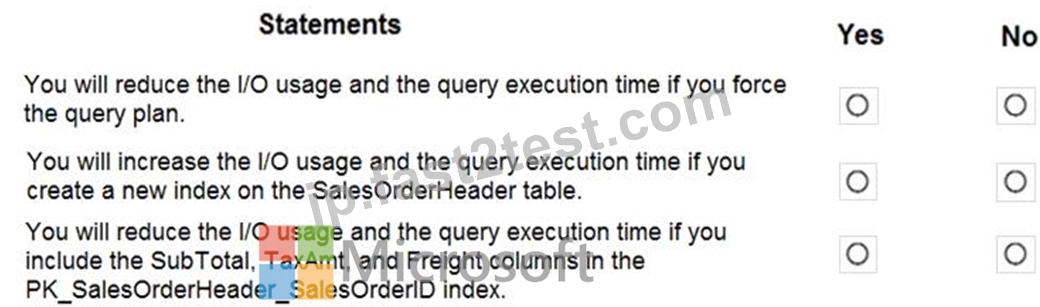
正解:
解説: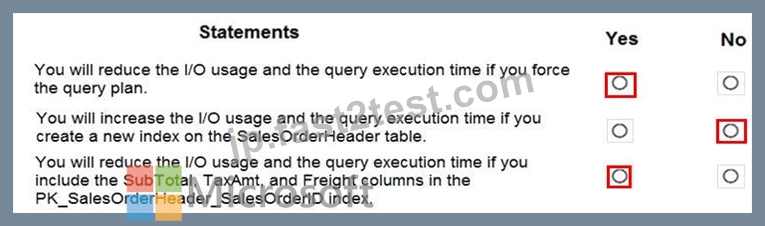
Reference:
https://docs.microsoft.com/en-us/sql/relational-databases/performance/monitoring-performance-by-using-the-query-store
質問 # 142
......
Microsoft DP-300認定試験は、データベース管理者、データベース開発者、およびMicrosoft Azureと協力するIT専門家に最適です。認定試験は、あなたのキャリアの見通しを強化し、潜在的な雇用主に専門知識を実証する素晴らしい方法です。 DP-300試験に合格すると、Microsoft認定を受けたAzure Database Administrator Associateになります。これは、業界で非常に尊敬される認定です。
Microsoft DP-300試験は、Microsoft Azureでリレーショナルデータベースを管理する専門知識を実証したい専門家向けに設計されています。この認定は、セキュリティの実装、バックアップの管理、データベースの復元、パフォーマンスの最適化、データベースの監視とトラブルシューティングなどのタスクを実行する候補者の能力を検証します。 DP-300試験では、Azure SQLデータベース、Azure SQL Managedインスタンス、Azure Synapse分析など、Azureで使用されている最新のテクノロジーで候補者の知識とスキルを測定します。
最新の2023年最新の実際に出ると確認されたDP-300問題集で100%無料DP-300試験問題集:https://jp.fast2test.com/DP-300-premium-file.html
無料提供中2023年最新の無料更新されたMicrosoft DP-300試験問題と解答:https://drive.google.com/open?id=18IZ0N8r5xfwn5AOauieouHzlIgwObtzB