

あなたを合格させるAzure Cosmos DB Developer Specialty DP-420日本語試験問題集で2024年08月22日には123問あります
DP-420日本語無料試験学習ガイド!(更新された123問あります)
質問 # 32
account1 という名前の Azure Cosmos DB for NoSQL アカウントに、container1 という名前のコンテナーがあります。
C# および Java の展示に示されているように、暗号化ポリシーを使用して、Always Encrypted を使用するようにコンテナー 1 を構成します。 (C# の暗号化ポリシーを表示するには、「C#」タブをクリックします。Java の暗号化ポリシーを表示するには、「Java」タブをクリックします。)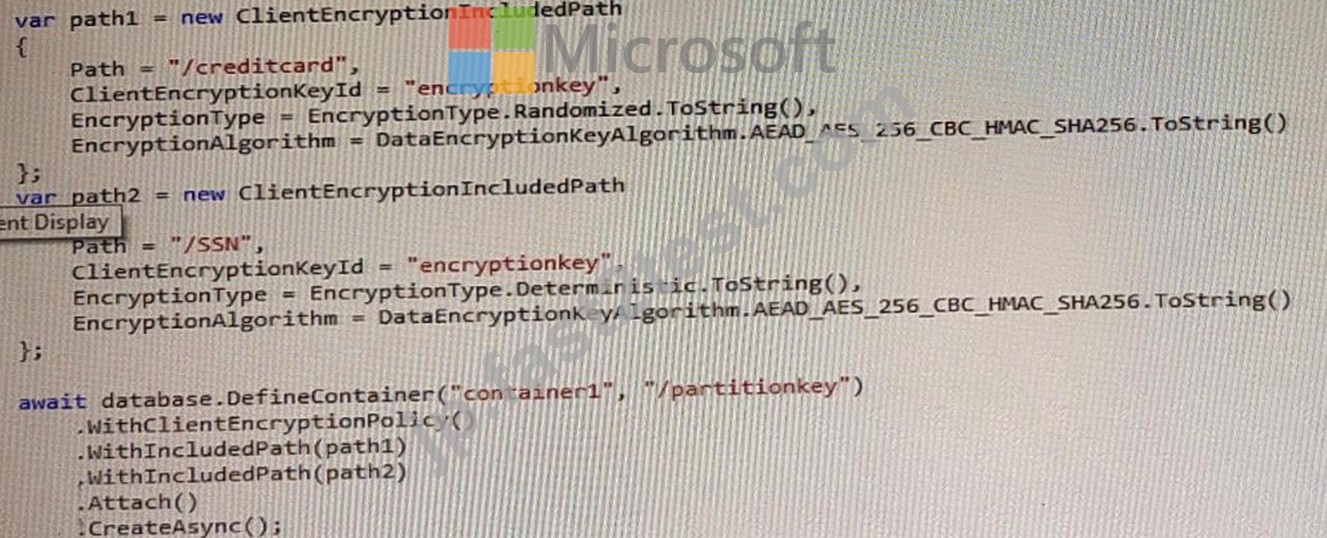

次の各ステートメントについて、そのステートメントが true の場合は [はい] を選択します。それ以外の場合は、「いいえ」を選択します。
注: 正しく選択するたびに 1 ポイントの価値があります。
正解:
解説:
Explanation:
According to the Azure Cosmos DB documentation1, Always Encrypted is a feature designed to protect sensitive data, such as credit card numbers or national identification numbers, stored in Azure Cosmos DB.
Always Encrypted allows clients to encrypt sensitive data inside client applications and never reveal the encryption keys to the database.
To use Always Encrypted, you need to define an encryption policy for each container that specifies which properties should be encrypted and which data encryption keys (DEK) should be used. The DEKs are stored in Azure Cosmos DB and are wrapped by customer-managed keys (CMK) that are stored in Azure Key Vault.
Based on the encryption policy shown in the exhibits, the creditcard property is encrypted with a DEK named dek1, and the SSN property is encrypted with a DEK named dek2. Both DEKs are wrapped by a CMK named cmk1.
To answer your statements:
* You can perform a query that filters on the creditcard property = No. This is because the creditcard property is encrypted and cannot be used for filtering or sorting operations1.
* You can perform a query that filters on the SSN property = No. This is also because the SSN property is encrypted and cannot be used for filtering or sorting operations1.
* An application can be allowed to read the creditcard property while being restricted from reading the SSN property = Yes. This is possible by using different CMKs to wrap different DEKs and applying access policies on the CMKs in Azure Key Vault. For example, if you use cmk2 to wrap dek2 instead of cmk1, you can grant an application access to cmk1 but not cmk2, which means it can read the creditcard property but not the SSN property2.
質問 # 33
account1 に対してマルチリージョン書き込みを構成します。
App1 が account1 の新しい構成をサポートしていることを確認する必要があります。ソリューションは、ビジネス要件と製品カタログの要件を満たしている必要があります。
あなたは何をするべきか?
- A. con-product コンテナーと con-productVendor コンテナーに割り当てられる 1 秒あたりの要求ユニット数 (RU/秒) を増やします。
- B. accountl のデフォルトの整合性レベルを限界のある古い状態に設定します。
- C. App1 の接続ポリシーを変更します。
- D. プライベート エンドポイント接続を作成します。
正解:A
解説:
App1 queries the con-product and con-productVendor containers.
Note: Request unit is a performance currency abstracting the system resources such as CPU, IOPS, and memory that are required to perform the database operations supported by Azure Cosmos DB.
Scenario:
Develop an app named App1 that will run from all locations and query the data in account1.
Once multi-region writes are configured, maximize the performance of App1 queries against the data in account1.
Whenever there are multiple solutions for a requirement, select the solution that provides the best performance, as long as there are no additional costs associated.
Reference:
https://docs.microsoft.com/en-us/azure/cosmos-db/consistency-levels
質問 # 34
あなたは、アプリケーションの更新によって引き起こされる現在の問題のトラブルシューティングを行っています。
アプリケーションの機能に影響を与えることなく、アプリケーションの更新の問題に対処できるアクションはどれですか?
- A. account1 のデフォルトの整合性レベルを「strong」に設定します。
- B. カスタム インデックス作成ポリシーを製品コンテナに追加します。
- C. コンプロダクト コンテナーの有効期間を有効にします。
- D. account1 のデフォルトの整合性レベルを限界のある古い状態に設定します。
正解:D
解説:
Bounded staleness is frequently chosen by globally distributed applications that expect low write latencies but require total global order guarantee. Bounded staleness is great for applications featuring group collaboration and sharing, stock ticker, publish-subscribe/queueing etc.
Scenario: Application updates in con-product frequently cause HTTP status code 429 "Too many requests".
You discover that the 429 status code relates to excessive request unit (RU) consumption during the updates.
Reference:
https://docs.microsoft.com/en-us/azure/cosmos-db/consistency-levels
質問 # 35
Azure Synapse Analytics には、ノートブックで次の Python コードを実行する Apache Spark プールがあります。
次の各ステートメントについて、そのステートメントが true の場合は [はい] を選択します。それ以外の場合は、「いいえ」を選択します。
注: 正しく選択するたびに 1 ポイントの価値があります。
正解:
解説:
Explanation:
New and updated orders will be added to contoso-erp.orders: Yes
The code performs bulk data ingestion from contoso-app: No
Both contoso-app and contoso-erp have Analytics store enabled: Yes
The code uses the spark.readStream method to read data from a container named orders in a database named contoso-app. The data is then filtered by a condition and written to another container named orders in a database named contoso-erp using the spark.writeStream method. The write mode is set to "append", which means that new and updated orders will be added to the destination container1.
The code does not perform bulk data ingestion from contoso-app, but rather stream processing. Bulk data ingestion is a process of loading large amounts of data into a data store in batches. Stream processing is a process of continuously processing data as it arrives in real-time2.
Both contoso-app and contoso-erp have Analytics store enabled, because they are both accessed by Spark pools using the spark.cosmos.oltp method. This method requires that the containers have Analytics store enabled, which is a feature that allows Spark pools to query data stored in Azure Cosmos DB containers using SQL APIs3.
質問 # 36
Azure Cosmos DB Core (SQL) API アカウントにデータベースがあります。データベースは 2 時間ごとにバックアップされます。
ポイントインタイム復元をサポートするソリューションを実装する必要があります。
まず何をすべきでしょうか?
- A. アカウントのポイント イン タイム リストア設定を構成します。
- B. 定期的なバックアップ ポリシーを持つ新しいアカウントを作成します。
- C. アカウントの継続的バックアップを有効にします。
- D. アカウントのバックアップと復元の設定を構成します。
正解:C
解説:
Reference: https://docs.microsoft.com/en-us/azure/cosmos-db/provision-account-continuous-backup
質問 # 37
計画された変更をサポートし、ビジネス要件を満たすために、account2 の容量モードとスケール構成を選択する必要があります。何を選択すればよいでしょうか?回答するには、回答領域で適切なオプションを選択してください。注: 正しく選択するたびに 1 ポイントの価値があります。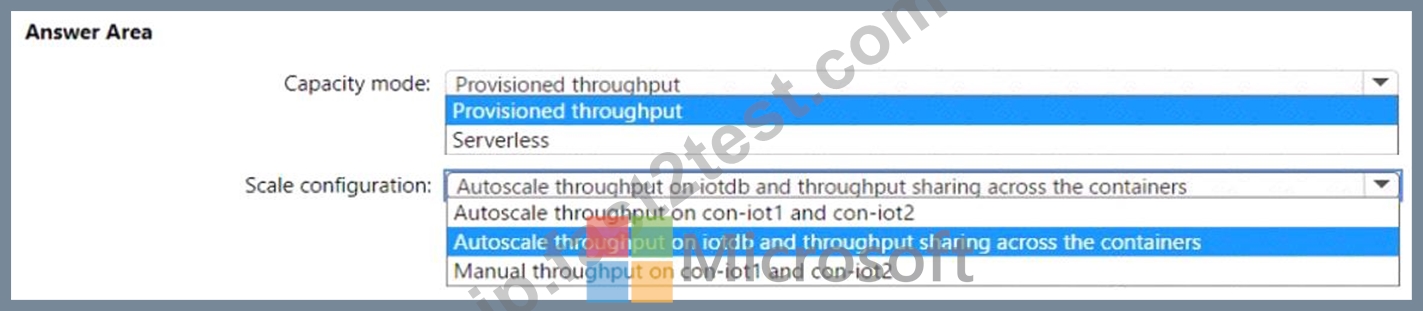
正解:
解説:
Explanation:
質問 # 38
Azure Cosmos DB Core (SQL) API アカウントにコンテナーがあります。
オプティミスティック同時実行を使用してドキュメントを置き換えるには、Azure Cosmos DB SDK を使用する必要があります。
コードには何を含めるべきでしょうか?回答するには、回答領域で適切なオプションを選択してください。
注: 正しく選択するたびに 1 ポイントの価値があります。
正解:
解説:
Explanation:
Box 1: ConsistencyLevel
The ItemRequestOptions Class ConsistencyLevel property gets or sets the consistency level required for the request in the Azure Cosmos DB service.
Azure Cosmos DB offers 5 different consistency levels. Strong, Bounded Staleness, Session, Consistent Prefix and Eventual - in order of strongest to weakest consistency.
Box 2: _etag
The ItemRequestOptions class helped us implement optimistic concurrency by specifying that we wanted the SDK to use the If-Match header to allow the server to decide whether a resource should be updated. The If-Match value is the ETag value to be checked against. If the ETag value matches the server ETag value, the resource is updated.
Reference:
https://docs.microsoft.com/en-us/dotnet/api/microsoft.azure.cosmos.itemrequestoptions
https://cosmosdb.github.io/labs/dotnet/labs/10-concurrency-control.html
質問 # 39
製品カタログの要件を満たすソリューションを実装する必要があります。
競合解決ポリシーを実装するにはどうすればよいですか。
- A. コンプロダクト コンテナのインデックス ポリシー内のすべてのフィールドのインデックス作成を無効にします。
- B. 頻繁に変更されるフィールドを、製品コンテナのインデックス ポリシーから削除します。
- C. 新しいコンテナを作成し、製品カタログ データを新しいコンテナに移行します。
- D. account1 のデフォルトの整合性レベルを最終に設定します。
正解:D
質問 # 40
Azure Cosmos DB Core (SQL) API アカウントにデータを保存するアプリがあります。このアプリは、大きな結果セットを返すクエリを実行します。
ページネーションを使用して、完全な結果セットをアプリに返す必要があります。結果の各ページは 80 項目を返す必要があります。
どの 3 つのアクションを順番に実行する必要がありますか?回答するには、アクションのリストから適切なアクションを回答領域に移動し、正しい順序で並べます。
正解:
解説:
Explanation: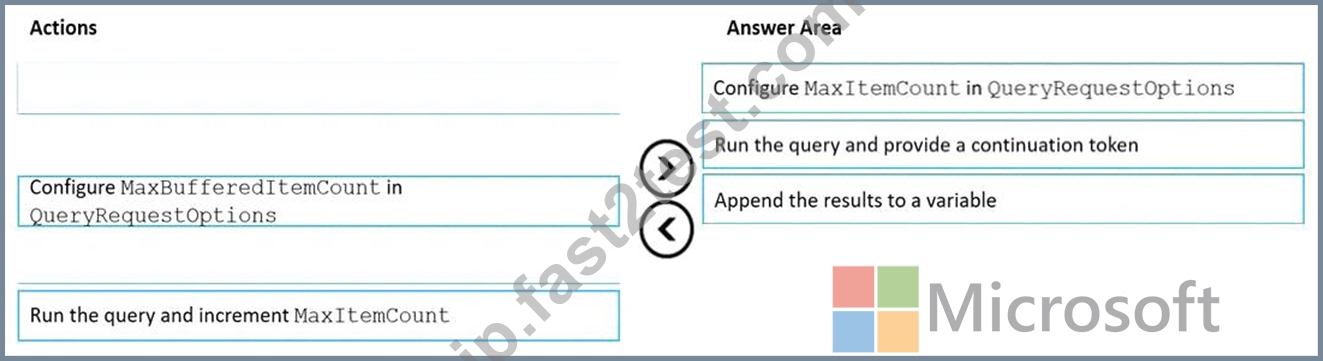
Step 1: Configure the MaxItemCount in QueryRequestOptions
You can specify the maximum number of items returned by a query by setting the MaxItemCount. The MaxItemCount is specified per request and tells the query engine to return that number of items or fewer.
Box 2: Run the query and provide a continuation token
In the .NET SDK and Java SDK you can optionally use continuation tokens as a bookmark for your query's progress. Azure Cosmos DB query executions are stateless at the server side and can be resumed at any time using the continuation token.
If the query returns a continuation token, then there are additional query results.
Step 3: Append the results to a variable
Reference: https://docs.microsoft.com/en-us/azure/cosmos-db/sql/sql-query-pagination
質問 # 41
Azure Cosmos DB Core (SQL) API アカウントには、IoT データを保存する telemetry という名前のデータベースがあります。
データベースには、readings と devices という名前の 2 つのコンテナーが含まれています。
読み物の文書は次のような構造になっています。
ID
デバイスID
タイムスタンプ
所有者
メジャー (配列)
- タイプ
- 価値
- メトリックID
デバイス内のドキュメントは次の構造になっています。
ID
デバイスID
所有者
- 所有者
- 電子メールアドレス
- 名前
ブランド
モデル
次の各ステートメントについて、そのステートメントが true の場合は [はい] を選択します。それ以外の場合は、「いいえ」を選択します。
注: 正しく選択するたびに 1 ポイントの価値があります。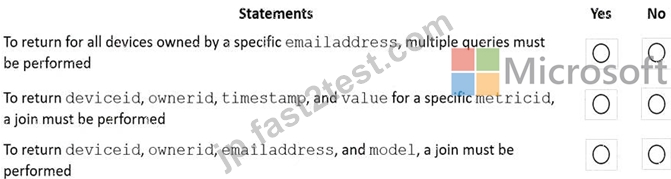
正解:
解説:
Explanation:
Box 1: Yes
Need to join readings and devices.
Box 2: No
Only readings is required. All required fields are in readings.
Box 3: No
Only devices is required. All required fields are in devices.
質問 # 42
Azure Cosmos DB SQL API Core (SQL) アカウントに開発に使用されるデータベースがあります。
データベースはバッチ処理で 1 日に 1 回変更されます。
最後のバッチプロセスが失敗した場合にデータベースを復元できることを確認する必要があります。ソリューションではコストを最小限に抑える必要があります。
バックアップ設定はどのように行うべきですか?回答するには、回答領域で適切なオプションを選択してください。
注: 正しく選択するたびに 1 ポイントの価値があります。
正解:
解説:
Explanation:
質問 # 43
Container1 という名前のコンテナーを含む Azure Cosmos DB for NoSQL アカウントがあります。
アイテム ID とパーティション キーのポイント読み取りを実行するキーと値のストアとして、container1 を使用する予定です。
コンテナーのインデックス作成ポリシーを定義する必要があります。ソリューションは次の要件を満たす必要があります。
*container1 に DefauitTimeToLive を設定する機能を提供します。
*実装時間を最小限に抑えます。
*コストを最小限に抑えます。
インデックス作成ポリシーの JSON 定義はどのように完了すればよいですか?回答するには、回答領域で適切なオプションを選択してください。
注: 正しく選択するたびに 1 ポイントの価値があります。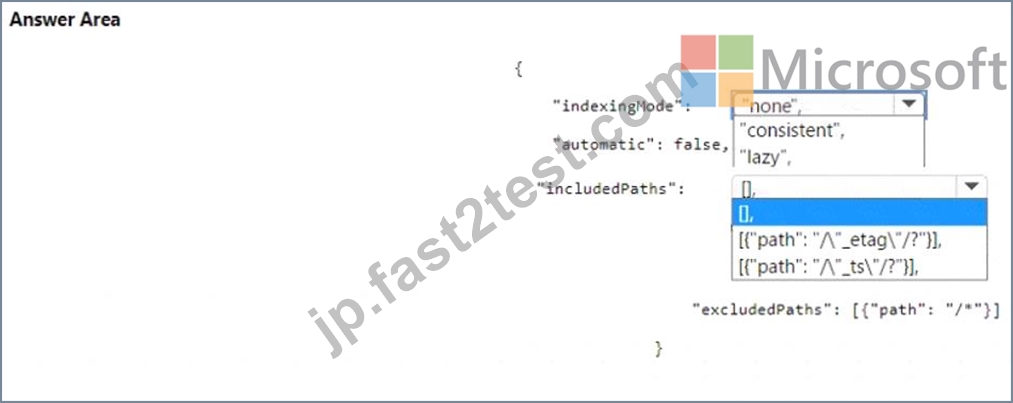
正解:
解説:
Explanation:
質問 # 44
それぞれに 1 つのデータベースを含む 2 つの Azure Cosmos DB Core (SQL) API アカウントをデプロイする予定です。
アカウントは次の表のように構成されます。
コストを最小限に抑えるために、各アカウント内でコンテナーをプロビジョニングするにはどうすればよいですか?回答するには、回答領域で適切なオプションを選択してください。
注: 正しく選択するたびに 1 ポイントの価値があります。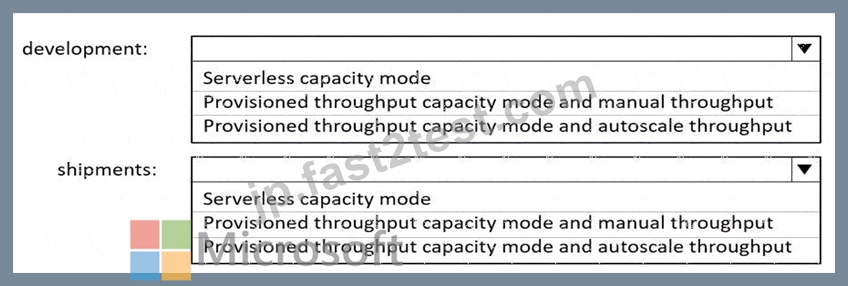
正解:
解説:
Explanation: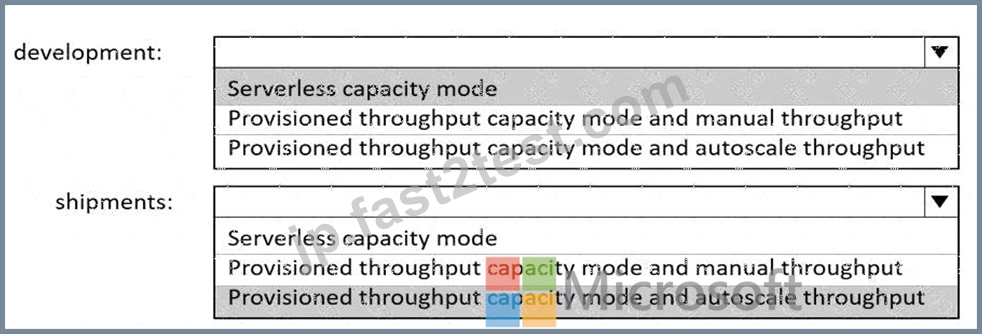
Box 1: Serverless capacity mode
Azure Cosmos DB serverless best fits scenarios where you expect intermittent and unpredictable traffic with long idle times. Because provisioning capacity in such situations isn't required and may be cost-prohibitive, Azure Cosmos DB serverless should be considered in the following use-cases:
Getting started with Azure Cosmos DB
Running applications with bursty, intermittent traffic that is hard to forecast, or low (<10%) average-to-peak traffic ratio Developing, testing, prototyping and running in production new applications where the traffic pattern is unknown Integrating with serverless compute services like Azure Functions Box 2: Provisioned throughput capacity mode and autoscale throughput The use cases of autoscale include:
Variable or unpredictable workloads: When your workloads have variable or unpredictable spikes in usage, autoscale helps by automatically scaling up and down based on usage. Examples include retail websites that have different traffic patterns depending on seasonality; IOT workloads that have spikes at various times during the day; line of business applications that see peak usage a few times a month or year, and more. With autoscale, you no longer need to manually provision for peak or average capacity.
Reference:
https://docs.microsoft.com/en-us/azure/cosmos-db/serverless
https://docs.microsoft.com/en-us/azure/cosmos-db/provision-throughput-autoscale#use-cases-of-autoscale
質問 # 45
Azure Cosmos OB for NoSQL データベースに運用データがあります。
データベース ユーザーは、ビジネス分析チームがデータベースに対して大規模な Apache Spark ベースのクエリを実行すると、データベースのパフォーマンスが大幅に低下すると報告しています。
Spark ベースのクエリの実行がデータベース ユーザーに与える影響を軽減する必要があります。
何を実装する必要がありますか?
- A. Spark コネクタ
- B. Azure Synapse リンク
- C. デフォルトの整合性レベル「Strong」
- D. デフォルトの一貫性レベルの一貫したプレフィックス
正解:B
質問 # 46
Azure Cosmos DB for NoSQL アカウントにコンテナーがあります。 1 秒あたり 30,000 要求ユニット (RU/秒) の手動スループットを持つデータベース。消費電流の詳細を次の表に示します。
PartitionKeyRangeID による正規化された RU 消費量 (%)

ドロップダウン メニューを使用して、図に示されている情報に基づいて各質問に答える回答の選択肢を選択します。注: 正しく選択するたびに 1 ポイントの価値があります。
正解:
解説:
Explanation: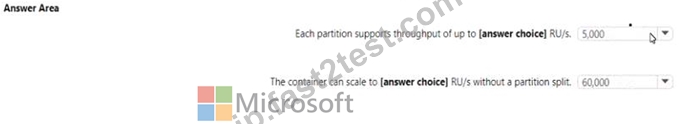
質問 # 47
次の例に示すように、Azure Cosmos DB Core (SQL) API アカウントのコンテナーにインデックスを付けるように Azure Cognitive Search を構成します。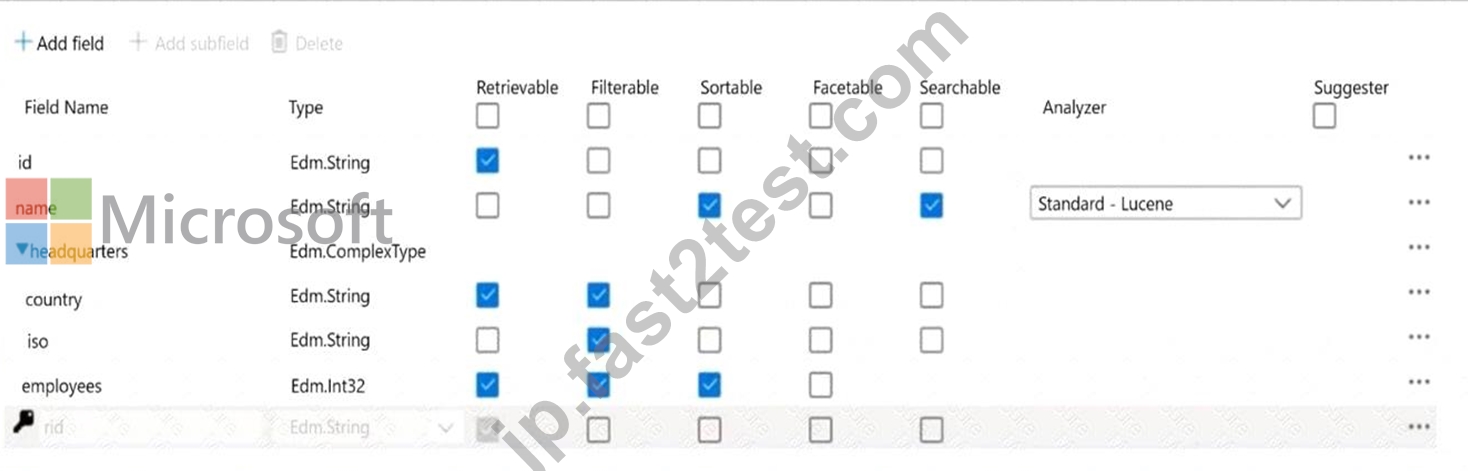
ドロップダウン メニューを使用して、図に示されている情報に基づいて各ステートメントを完成させる回答の選択肢を選択します。
注: 正しく選択するたびに 1 ポイントの価値があります。
正解:
解説:
Explanation:
Box 1: country
The country field is filterable.
Note: filterable: Indicates whether to enable the field to be referenced in $filter queries. Filterable differs from searchable in how strings are handled. Fields of type Edm.String or Collection(Edm.String) that are filterable do not undergo lexical analysis, so comparisons are for exact matches only.
Box 2: name
The name field is not Retrievable.
Retrievable: Indicates whether the field can be returned in a search result. Set this attribute to false if you want to use a field (for example, margin) as a filter, sorting, or scoring mechanism but do not want the field to be visible to the end user.
Note: searchable: Indicates whether the field is full-text searchable and can be referenced in search queries.
Reference: https://docs.microsoft.com/en-us/rest/api/searchservice/create-index
質問 # 48
Azure Cosmos DB for NoSQL アカウントに含まれる という名前のコンテナーがあります。
以下は、container1 内のドキュメントのサンプルです。
次の各ステートメントについて、そのステートメントが true の場合は [はい] を選択します。それ以外の場合は、「いいえ」を選択します。
注: 正しく選択するたびに 1 ポイントの価値があります。
正解:
解説:
Explanation:
質問 # 49
2 つのコンテナーを含む db1 という名前の Azure Cosmos DB データベースを作成する予定です。コンテナーの 1 つはブログ投稿を含み、もう 1 つはユーザーを含みます。ブログ投稿コンテナ内の各アイテムには次のものが含まれます。
* 単一のブログ投稿
* ブログ投稿に関連付けられたすべてのコメント
* ブログ投稿を作成し、コメントを追加したユーザーの名前。
データの整合性の問題を引き起こすことなく、ユーザー コンテナ内のユーザー名を更新するソリューションを設計する必要があります。
ソリューションでは、管理と開発の労力を最小限に抑える必要があります。ソリューションには何を含めるべきでしょうか?
回答するには、回答領域で適切なオプションを選択してください。
注: 正しく選択するたびに 1 ポイントの価値があります。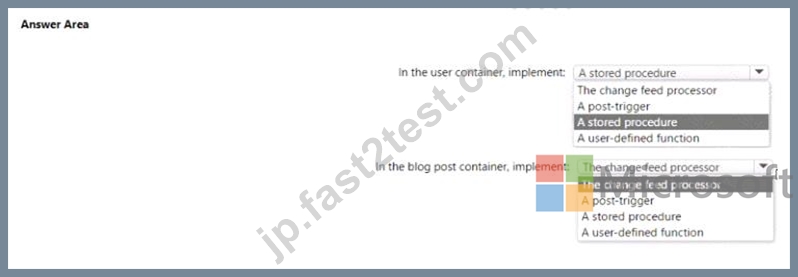
正解:
解説:
Explanation:
質問 # 50
コンテナー 1 という名前のコンテナーを含む Azure Cosmos DB データベースがあります。コンテナー 1 コンテナーは最大 20,000 RU/秒で構成されており、現在 240 GB のデータが含まれています。
現在の使用状況に基づいて、container1 のコストを見積もる必要があります。
何 RU/秒が請求されますか?
- A. 20,000
- B. 0
- C. 4.000
- D. 1
正解:C
質問 # 51
con-iot1 と con-iot2 を実装する予定です。
各コンテナーのデフォルトの存続期間設定を構成する必要があります。ソリューションは、LoT テレメトリ要件を満たしている必要があります。
何を設定すればよいでしょうか?回答するには、回答内の適切な選択肢を選択してください。 注: 正しい選択肢はそれぞれ 1 ポイントの価値があります。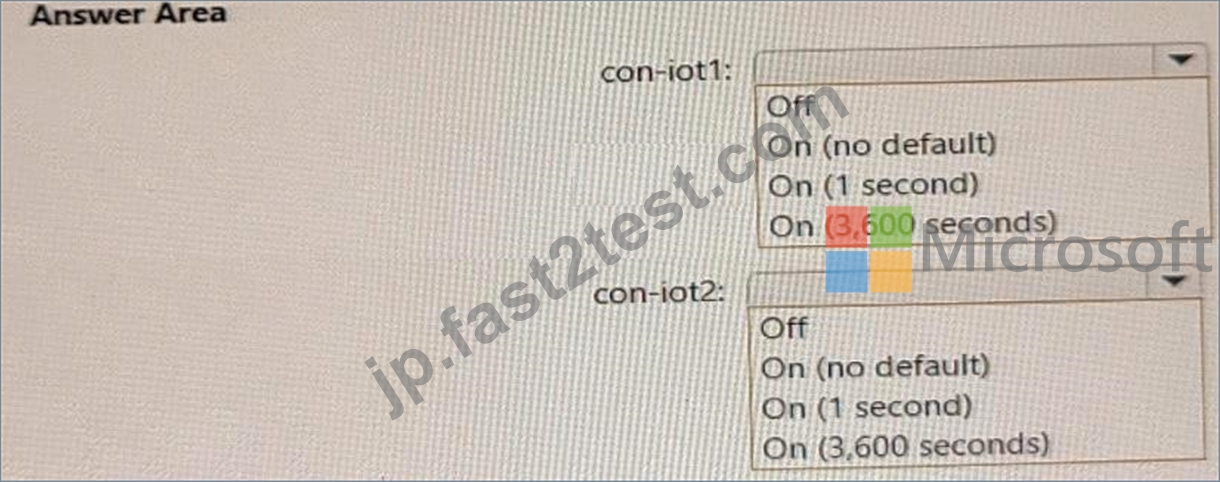
正解:
解説: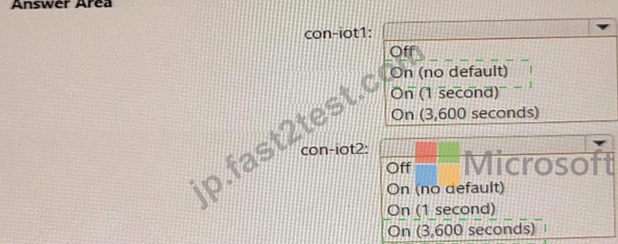
Explanation:
Box 1 = On (no default)For con-iot1, you need to configure the default TTL setting to On (no default), which means that items in this container do not expire by default, but you can override the TTL value on a per-item basis. This meets the requirement of retaining all telemetry data unless overridden1.
Box 2 = On (3600 seconds)For con-iot2, you need to configure the default TTL setting to On (3600 seconds), which means that items in this container will expire 3600 seconds (one hour) after their last modified time. This meets the requirement of deleting all telemetry data older than one hour1.
質問 # 52
Azure Cosmos 06 for NoSQL アカウントをクエリするアプリケーションがあります。
次の 2 つのクエリが頻繁に実行されることがわかります。
読み取りと書き込みによって消費される要求ユニット (RU) を最小限に抑える必要があります。何を作成する必要がありますか?
- A. (名前 DESC、タイムスタンプ ASC) の複合インデックス
- B. (名前 ASC タイムスタンプ ASC) の複合インデックスと (名前、タイムスタンプ ディスク) の複合インデックス
- C. (名前 ASC、タイムスタンプ DESC) の複合インデックス
- D. (名前 ASC、タイムスタンプ ASC) の複合インデックス
正解:D
質問 # 53
......
DP-420日本語問題集はAzure Cosmos DB Developer Specialty認証済み試験問題と解答:https://jp.fast2test.com/DP-420J-premium-file.html