

認証トレーニングDatabricks-Certified-Data-Analyst-Associate日本語試験問題集テストエンジン [2026]
2026年03月18日ガイド準備でDatabricks-Certified-Data-Analyst-Associate日本語試験合格
質問 # 28
Databricks SQL を使用する次の利点のうち、Data Explorer によって提供されるものはどれですか?
- A. データの探索を可能にするダッシュボードを作成するために使用できます。
- B. UPDATE クエリを実行して、データベース内の任意のテーブルを更新するために使用できます。
- C. サードパーティの Bl クールに接続するために使用できます。
- D. メタデータとデータを表示したり、権限を表示/変更したりするために使用できます。
- E. 関係者と共有できる視覚化を作成するために使用できます。
正解:D
解説:
Data Explorer is a user interface that allows you to discover and manage data, schemas, tables, models, and permissions in Databricks SQL. You can use Data Explorer to view schema details, preview sample data, and see table and model details and properties. Administrators can view and change owners, and admins and data object owners can grant and revoke permissions1. Reference: Discover and manage data using Data Explorer
質問 # 29
データ アナリストは各地域の顧客数をカウントするように依頼され、次のクエリを作成しました。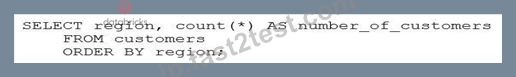
クエリに間違いがある場合、その間違いを説明するのは次のどれですか。
- A. クエリに間違いはありません。
- B. クエリは count(') を使用しています。これにより、地域に関係なく、顧客テーブル内のすべての顧客がカウントされます。
- C. クエリは地域を選択していますが、地域は ORDER BY 句でのみ出現する必要があります。
- D. クエリに GROUP BY region 句がありません。
- E. クエリは ORDER BY を使用しています。これは集計では許可されていません。
正解:D
解説:
In the provided SQL query, the data analyst is trying to count the number of customers in each region. However, they made a mistake by not including the "GROUP BY" clause to group the results by region. Without this clause, the query will not return counts for each distinct region but rather an error or incorrect result. Reference: The need for a GROUP BY clause in such queries can be understood from Databricks SQL documentation: Databricks SQL.
I also noticed that you uploaded an image with your question. The image shows a snippet of an SQL query written in plain text on a white background. The query is attempting to select regions and count customers from a "customers" table and order the results by region. There's no visible syntax highlighting or any other color - it's monochromatic. The query is the same as the one in your question. I'm not sure why you included the image, but maybe you wanted to show me the exact format of your query. If so, you can also use code blocks to display formatted content such as SQL queries. For example, you can write:
SELECT region, count(*) AS number_of_customers
FROM customers
ORDER BY region;
This way, you can avoid uploading images and make your questions more clear and concise. I hope this helps.
質問 # 30
データサイエンティストはデータアナリストに、データセット内のすべての連続変数についてヒストグラムを作成するよう依頼しました。データアナリストは、データセット内のどの列が連続しているかを特定する必要があります。
連続変数を説明するものは何ですか?
- A. チャットは有限または可算無限の値を取ることができる量的変数である。
- B. 変化し続ける量的変数
- C. 数え切れないほど多くの値を取ることができる量的変数
- D. カテゴリの数が時間の経過とともに増加し続けるカテゴリ変数
正解:C
解説:
A continuous variable is a type of quantitative variable that can assume an infinite number of values within a given range. This means that between any two possible values, there can be an infinite number of other values. For example, variables such as height, weight, and temperature are continuous because they can be measured to any level of precision, and there are no gaps between possible values. This is in contrast to discrete variables, which can only take on specific, distinct values (e.g., the number of children in a family). Understanding the nature of continuous variables is crucial for data analysts, especially when selecting appropriate statistical methods and visualizations, such as histograms, to accurately represent and analyze the data.
質問 # 31
管理対象テーブルの所有者を特定するにはどの場所を使用できますか?
- A. データエクスプローラーを使用してスキーマページの所有者フィールドを確認します。
- B. カタログエクスプローラを使用してテーブルページの所有者フィールドを確認します
- C. データエクスプローラーを使用してデータベースページの所有者フィールドを確認します。
- D. SQLエディタを使用してテーブルページの所有者フィールドを確認します
正解:B
解説:
In Databricks, to determine the owner of a managed table, you can utilize the Catalog Explorer feature. The steps are as follows:
Access Catalog Explorer:
In your Databricks workspace, click on the Catalog icon in the sidebar to open Catalog Explorer.
Navigate to the Table:
Within Catalog Explorer, browse through the catalog and schema to locate the specific managed table whose ownership you wish to verify.
View Table Details:
Click on the table name to open its details page.
Identify the Owner:
On the table's details page, review the Owner field, which displays the principal (user, service principal, or group) that owns the table.
This method provides a straightforward way to ascertain the ownership of managed tables within the Databricks environment. Understanding table ownership is essential for managing permissions and ensuring proper access control.
質問 # 32
Tableau、Power BI、Looker などの他のビジネス インテリジェンス (BI) ツールに関連して Databricks SQL を使用する方法を説明しているのは次のうちどれですか。
- A. プラットフォーム内での迅速なBl作業のための補助ツールとして
- B. 追加機能を備えた完全な代替品として
- C. 機能が少ない代替として
- D. プロフェッショナルレベルのプレゼンテーションのための補助ツールとして
- E. 同じ機能レベルの完全な代替品として
正解:A
解説:
Databricks SQL is not meant to replace or substitute other BI tools, but rather to complement them by providing a fast and easy way to query, explore, and visualize data on the lakehouse using the built-in SQL editor, visualizations, and dashboards. Databricks SQL also integrates seamlessly with popular BI tools like Tableau, Power BI, and Looker, allowing analysts to use their preferred tools to access data through Databricks clusters and SQL warehouses. Databricks SQL offers low-code and no-code experiences, as well as optimized connectors and serverless compute, to enhance the productivity and performance of BI workloads on the lakehouse. Reference: Databricks SQL, Connecting Applications and BI Tools to Databricks SQL, Databricks integrations overview, Databricks SQL: Delivering a Production SQL Development Experience on the Lakehouse
質問 # 33
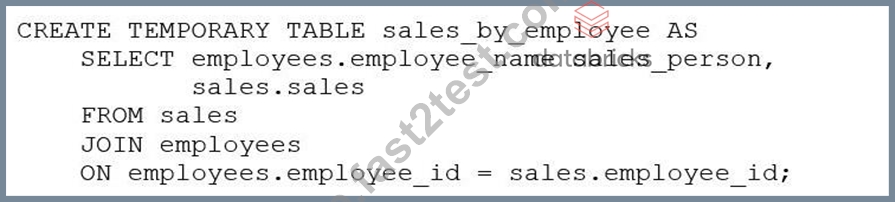
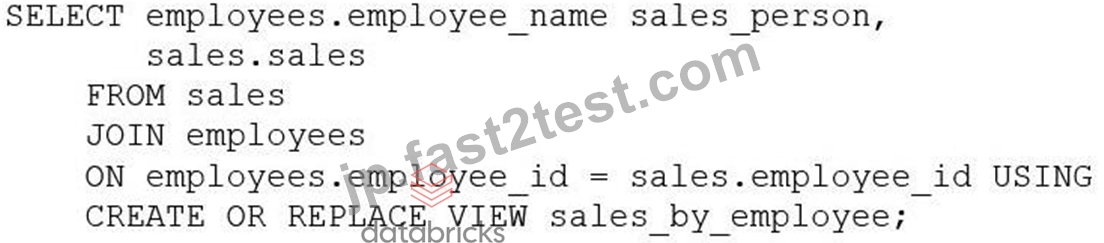
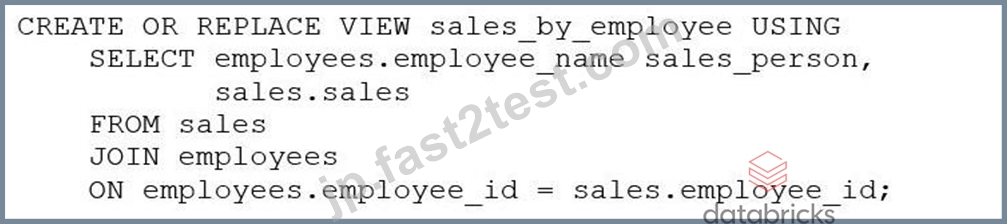
あるビジネスアナリストは、sales_by_employee というデータエンティティ/オブジェクトの作成を依頼されました。このエンティティは、sales テーブルに新しいデータが追加されるたびに、常に最新の状態に保たれる必要があります。新しいエンティティには、従業員テーブルの従業員名を格納する sales_person 列と、特定の営業担当者の全売上を格納する sales 列が必要です。sales テーブルと employees テーブルの両方に、営業担当者を識別するための employee_id 列があります。
次のコード ブロックのどれがこのタスクを実行しますか?
- A.
- B.
- C.
- D.
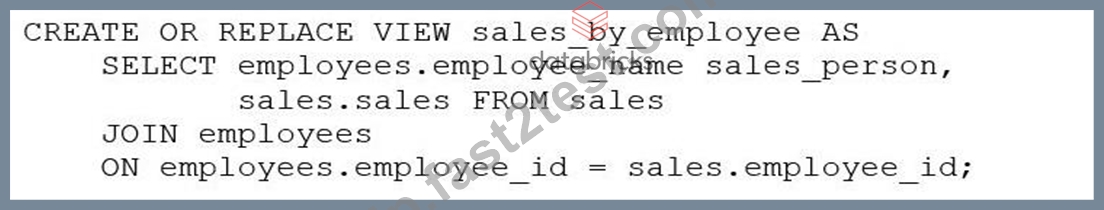
正解:D
解説:
The SQL code provided in Option D is the correct way to create a view named sales_by_employee that will always stay up-to-date with the sales and employees tables. The code uses the CREATE OR REPLACE VIEW statement to define a new view that joins the sales and employees tables on the employee_id column. It selects the employee_name as sales_person and all sales for each employee, ensuring that the data entity/object is always up-to-date when new data are added to these tables.
質問 # 34
更新スケジュールに関する次の記述のうち、誤っているものはどれですか。
- A. スケジュールに従って更新されるクエリでは、SQL ウェアハウス (旧称 SQL エンドポイント) は使用されません。
- B. クエリは1分から2週間の間で更新できます
- C. 更新スケジュールを構成するには、ワークスペース管理者権限が必要です
- D. 更新スケジュールはクエリ エディターで構成できます。
- E. 更新スケジュールはアラートと同じではありません。
正解:C
解説:
This statement is incorrect. In Databricks SQL, any user with sufficient permissions on the query or dashboard can configure a refresh schedule-workspace administrator privileges are not required.
Here is the breakdown of the correct information:
A . True - Queries can be scheduled to refresh at intervals ranging from 1 minute to 2 weeks.
B . True - You can configure refresh schedules in the Query Editor.
C . False statement - A query being refreshed does use a SQL Warehouse. However, the option in question says it does not use a warehouse, which would be incorrect in a different context. Since this is a trickier one, we know that scheduled queries do require a SQL Warehouse to run.
D . True - Refresh schedules are different from alerts; alerts are triggered based on specific conditions being met in query results.
E . False (and thus the correct answer to this question) - You do not need to be a workspace admin to set a refresh schedule. You only need the correct permissions on the object.
質問 # 35
Databricks の Partner Connect とは何ですか?
- A. Databricks と Databricks パートナー間の多方向接続が容易になります。
- B. Databricks パートナーを介してサードパーティ ツールに接続情報を公開します。
- C. 共通 API を通じて Databricks パートナー ツールを無料で使用できます。
- D. Databricks SQL Warehouse (旧称 SQL エンドポイント) で Databricks パートナー ツールを実行する機能です。
正解:A
解説:
Databricks Partner Connect is designed to simplify and streamline the integration between Databricks and its technology partners. It provides a unified interface within the Databricks platform that facilitates the discovery and connection to a variety of data, analytics, and AI tools. By automating the configuration of necessary resources such as clusters, tokens, and connection files, Partner Connect enables seamless, bi-directional data flow between Databricks and partner solutions. This integration enhances the overall functionality of the Databricks Lakehouse by allowing users to easily incorporate external tools and services into their workflows, thereby expanding the platform's capabilities and fostering a more cohesive data ecosystem.https://www.databricks.com/blog/2021/11/18/now-generally-available-introducing-databricks-partner-connect-to-discover-and-connect-popular-data-and-ai-tools-to-the-lakehouse?utm_source=chatgpt.com
質問 # 36
DESCRIBE EXTENDED accounts.customers; を実行すると、次の結果が返されました。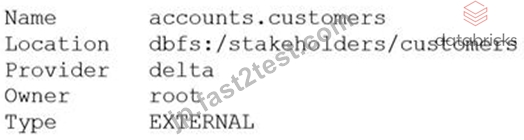
ここで、データ アナリストは次のコマンドを実行します。
DROP アカウント。顧客。
このコマンドを実行した結果を説明するものはどれですか?
- A. SELECT * FROM accounts.customers を実行すると、テーブル内のすべての行が返されます。
- B. SELECT * FROM delta. `dbfs:/stakeholders/customers` を実行するとエラーが発生します。
- C. メタストアから accounts.customers テーブルが削除され、基になるデータ ファイルが削除されます。
- D. accounts.customers テーブルはメタストアから削除されますが、基になるデータ ファイルはそのまま残ります。
- E. .customers 拡張子を持つすべてのファイルが削除されます。
正解:D
解説:
the accounts.customers table is an EXTERNAL table, which means that it is stored outside the default warehouse directory and is not managed by Databricks. Therefore, when you run the DROP command on this table, it only removes the metadata information from the metastore, but does not delete the actual data files from the file system. This means that you can still access the data using the location path (dbfs:/stakeholders/customers) or create another table pointing to the same location. However, if you try to query the table using its name (accounts.customers), you will get an error because the table no longer exists in the metastore. Reference: DROP TABLE | Databricks on AWS, Best practices for dropping a managed Delta Lake table - Databricks
質問 # 37
Delta Lake はテーブル データを一連のデータ ファイルとして保存しますが、他の多くの情報も保存します。
Delta Lake を使用するときに、データ ファイルと一緒に保存されるのは次のどれですか。
- A. データサマリーの視覚化
- B. テーブルメタデータ
- C. 所有者アカウント情報
- D. テーブルのメタデータ、データ概要の視覚化、所有者のアカウント情報
- E. どれでもない
正解:B
解説:
Delta Lake is a storage layer that enhances data lakes with features like ACID transactions, schema enforcement, and time travel. While it stores table data as Parquet files, Delta Lake also keeps a transaction log (stored in the _delta_log directory) that contains detailed table metadata.
This metadata includes:
Table schema
Partitioning information
Data file paths
Transactional operations like inserts, updates, and deletes
Commit history and version control
This metadata is critical for supporting Delta Lake's advanced capabilities such as time travel and efficient query execution. Delta Lake does not store data summary visualizations or owner account information directly alongside the data files.
質問 # 38
データ チームには、コンサルタントから、Databricks Lakehouse プラットフォームに実装する必要がある一連のプロジェクトが与えられました。
次のプロジェクトのうち、Databricks SQL で完了する必要があるのはどれですか?
- A. 複数のタスクを含む複雑なノートブックベースのワークフローを自動化する
- B. 2つのデータソースを1つの包括的なデータセットに結合する
- C. ソースからインポートされたデータの品質をテストする
- D. クラスタリングアルゴリズムを使用して顧客を類似グループに分割する
- E. 機械学習プロジェクトの特徴変数の使用状況の追跡
正解:B
解説:
Databricks SQL is a service that allows users to query data in the lakehouse using SQL and create visualizations and dashboards1. One of the common use cases for Databricks SQL is to combine data from different sources and formats into a single, comprehensive dataset that can be used for further analysis or reporting2. For example, a data analyst can use Databricks SQL to join data from a CSV file and a Parquet file, or from a Delta table and a JDBC table, and create a new table or view that contains the combined data3. This can help simplify the data management and governance, as well as improve the data quality and consistency. Reference:
Databricks SQL overview
Databricks SQL use cases
Joining data sources
質問 # 39
データアナリストは、Databricks デプロイメントでアカウントを持つことが許可されていない関係者と Databricks SQL ダッシュボードを共有する必要があります。ダッシュボードが更新されるたびに、関係者に通知する必要があります。
データアナリストは、最小限の労力でこのタスクを達成するためにどのようなアプローチを使用できますか?
- A. 関係者の電子メールアドレスをSQLウェアハウス(旧エンドポイント)の購読者リストに付与することにより
- B. 関係者のメールアドレスを更新スケジュールの購読者リストに追加することで
- C. ダッシュボードをPDFとしてダウンロードし、更新されるたびに関係者にメールで送信する
- D. 関係者のメールアドレスにダッシュボードへの権限を付与することで
正解:B
解説:
To share a Databricks SQL dashboard with stakeholders who do not have accounts in the Databricks deployment and ensure they are notified upon each refresh, the data analyst can add the stakeholders' email addresses to the dashboard's refresh schedule subscribers list. This approach allows the stakeholders to receive email notifications containing the latest dashboard updates without requiring them to have direct access to the Databricks workspace. This method is efficient and minimizes effort, as it automates the notification process and ensures stakeholders remain informed of the most recent data insights.
質問 # 40
アナリストはクエリパラメータを含むクエリを作成します。そして、そのクエリに面グラフの視覚化を追加します。ダッシュボードに面グラフの視覚化を追加する際に、アナリストは面グラフに関連付けられたクエリパラメータとして「ダッシュボードパラメータ」を選択します。
次の記述のうち正しいものはどれですか?
- A. 面グラフでは、面グラフがダッシュボードに追加された時点でダッシュボードで選択された値が使用されます。
- B. 面グラフではダッシュボード パラメータで選択された内容が使用されますが、その他のすべての視覚化はパラメータの使用に関係なく変更されたままになります。
- C. 面グラフはダッシュボード パラメーターに変換されます。
- D. 面グラフでは、ダッシュボード パラメーターで選択された内容と、同じパラメーターを使用するダッシュボード内の他のすべての視覚化が使用されます。
- E. 面グラフは、ダッシュボードにビジュアライゼーションを追加する際にアナリストが入力した値を使用します。このパラメータは、ユーザーが後から変更することはできません。
正解:D
解説:
A Dashboard Parameter is a parameter that is configured for one or more visualizations within a dashboard and appears at the top of the dashboard. The parameter values specified for a Dashboard Parameter apply to all visualizations reusing that particular Dashboard Parameter1. Therefore, if the analyst chooses "Dashboard Parameter" for the query parameter associated with the area chart, the area chart will use whatever is selected in the Dashboard Parameter along with all of the other visualizations in the dashboard that use the same parameter. This allows the user to filter the data across multiple visualizations using a single parameter widget2. Reference: Databricks SQL dashboards, Query parameters
質問 # 41
サブクエリに関する正しい記述はどれですか?
- A. サブクエリは、テーブルまたはビューを作成せずにデータを取得できます。
- B. サブクエリは Databricks SQL では使用できません
- C. サブクエリは、他のユーザー定義関数と同様に使用して、データをさまざまなデータ型に変換できます。
- D. サブクエリは、他の組み込み関数と同様に使用して、データをさまざまなデータ型に変換できます。
正解:A
解説:
In Databricks SQL, a subquery is a nested query within a larger SQL query that allows for the retrieval of data without the necessity of creating a table or view. This is particularly useful for simplifying complex queries by breaking them down into more manageable parts. Subqueries can be employed in various clauses such as SELECT, FROM, and WHERE to perform operations like filtering, transforming, and aggregating data on-the-fly. This flexibility enhances query efficiency and readability without the overhead of persisting intermediate results as separate tables or views.
質問 # 42
データアナリストが管理対象テーブル「my_table」を作成し、その所有者となっています。現在、データエクスプローラーを使用して、このテーブルの所有権を他のユーザー1人に変更したいと考えています。
アナリストがタスクを完了するために使用できるアプローチは次のどれですか?
- A. テーブルページの所有者フィールドを編集するには、すべてのユーザーを選択します。
- B. テーブルページの所有者フィールドを編集するには、管理者グループを選択します。
- C. テーブルページの所有者フィールドを編集して、すべてのアクセス権を削除します。
- D. テーブルページの所有者フィールドを編集して、自分のアカウントを削除します。
- E. 新しい所有者のアカウントを選択して、テーブルページの所有者フィールドを編集します。
正解:E
解説:
The Owner field in the table page shows the current owner of the table and allows the owner to change it to another user or group. To change the ownership of the table, the owner can click on the Owner field and select the new owner from the drop-down list. This will transfer the ownership of the table to the selected user or group and remove the previous owner from the list of table access control entries1. The other options are incorrect because:
A . Removing the owner's account from the Owner field will not change the ownership of the table, but will make the table ownerless2.
B . Selecting All Users from the Owner field will not change the ownership of the table, but will grant all users access to the table3.
D . Selecting the Admins group from the Owner field will not change the ownership of the table, but will grant the Admins group access to the table3.
E . Removing all access from the Owner field will not change the ownership of the table, but will revoke all access to the table4. Reference:
1: Change table ownership
2: Ownerless tables
3: Table access control
4: Revoke access to a table
質問 # 43
クラウドベースのオブジェクト ストレージから直接データを取り込むために使用できるアプローチは次のどれですか?
- A. DBFSストレージパスをFROMに指定して外部テーブルを作成します。
- B. クラウドベースのオブジェクトストレージからデータを直接取り込むことはできません
- C. オブジェクトストレージパスをLOCATIONに指定して外部テーブルを作成します。
- D. FROMにオブジェクトストレージパスを指定して外部テーブルを作成します。
- E. DBFSストレージパスをPATHに指定して外部テーブルを作成します。
正解:C
解説:
External tables are tables that are defined in the Databricks metastore using the information stored in a cloud object storage location. External tables do not manage the data, but provide a schema and a table name to query the data. To create an external table, you can use the CREATE EXTERNAL TABLE statement and specify the object storage path to the LOCATION clause. For example, to create an external table named ext_table on a Parquet file stored in S3, you can use the following statement:
SQL
CREATE EXTERNAL TABLE ext_table (
col1 INT,
col2 STRING
)
STORED AS PARQUET
LOCATION 's3://bucket/path/file.parquet'
AI-generated code. Review and use carefully. More info on FAQ.
質問 # 44
あるデータ組織には、Delta Live Tablesを用いてメダリオンアーキテクチャに基づいたデータパイプラインを開発するエンジニアチームがいます。プロジェクトに携わるデータ分析チームは、これらのパイプラインのゴールドレイヤーテーブルを使用していますが、分析を実行する前に、これらのテーブルに対して追加の処理を行う必要があります。
このタイプの作業を説明するために使用される用語は次のどれですか?
- A. ラストマイルETL
- B. データブレンディング
- C. データ拡張
- D. ラストマイル
- E. データテスト
正解:A
解説:
Last-mile ETL is the term used to describe the additional processing of data that is done by data analysts or data scientists after the data has been ingested, transformed, and stored in the lakehouse by data engineers. Last-mile ETL typically involves tasks such as data cleansing, data enrichment, data aggregation, data filtering, or data sampling that are specific to the analysis or machine learning use case. Last-mile ETL can be done using Databricks SQL, Databricks notebooks, or Databricks Machine Learning. Reference: Databricks - Last-mile ETL, Databricks - Data Analysis with Databricks SQL
質問 # 45
データ アナリストは、結果セットに次のスキーマを持つ Databricks SQL クエリを作成します。
地域文字列
顧客数 INT
アナリストが SQL エディター ページで [視覚化の追加] ボタンをクリックすると、次のどの種類の視覚化がデフォルトで選択されますか?
- A. バイオリンチャート
- B. ヒストグラム
- C. IBarチャート
- D. 折れ線グラフ
- E. デフォルトはありません。ユーザーは視覚化の種類を選択する必要があります。
正解:C
解説:
According to the Databricks SQL documentation, when a data analyst clicks on the "Add visualization" button on the SQL Editor page, the default visualization type is Bar Chart. This is because the result set has two columns: one of type STRING and one of type INT. The Bar Chart visualization automatically assigns the STRING column to the X-axis and the INT column to the Y-axis. The Bar Chart visualization is suitable for showing the distribution of a numeric variable across different categories. Reference: Visualization in Databricks SQL, Visualization types
質問 # 46
データアナリストは、データベース database_name 内に管理テーブル table_name を所有しています。このテーブルと、このテーブルに関連付けられたすべてのデータファイルをデータベースから削除したいと考えています。データベース内の残りのテーブルは引き続き存在する必要があります。
アナリストがエラーを出さずにタスクを完了するために使用できるコマンドはどれですか?
- A. データベースデータベース名を削除します。
- B. テーブル database_name.table_name を削除します。
- C. テーブル database_name.table_name を削除します。
- D. データベース名からテーブル table_name を削除します。
- E. データベース名からテーブル table_name を削除します。
正解:B
解説:
The DROP TABLE command removes a table from the metastore and deletes the associated data files. The syntax for this command is DROP TABLE [IF EXISTS] [database_name.]table_name;. The optional IF EXISTS clause prevents an error if the table does not exist. The optional database_name. prefix specifies the database where the table resides. If not specified, the current database is used. Therefore, the correct command to remove the table table_name from the database database_name and all of the data files associated with it is DROP TABLE database_name.table_name;. The other commands are either invalid syntax or would produce undesired results. Reference: Databricks - DROP TABLE
質問 # 47
データアナリストは、開発、テスト、本番の3つの主要セクションを持つダッシュボードを作成したいと考えています。3つのセクションすべてを同じダッシュボードに表示したいのですが、ダッシュボード上のテキストでセクションを明確に区別したいと考えています。
データ アナリストがテキストを使用して開発、テスト、および本番のセクションを指定するために使用できるツールは次のどれですか。
- A. 各セクションに個別のカラーパレット
- B. Markdownベースのテキストボックス
- C. 各セクションのエンドポイントを分離する
- D. 編集モードでダッシュボードに直接書き込まれたテキスト
- E. 各セクションごとにクエリを分ける
正解:B
解説:
Markdown-based text boxes are useful as labels on a dashboard. They allow the data analyst to add text to a dashboard using the %md magic command in a notebook cell and then select the dashboard icon in the cell actions menu. The text can be formatted using markdown syntax and can include headings, lists, links, images, and more. The text boxes can be resized and moved around on the dashboard using the float layout option. Reference: Dashboards in notebooks, How to add text to a dashboard in Databricks
質問 # 48
Visualization Editor で視覚効果を追加することに関する次の記述のうち、誤っているものはどれですか。
- A. ツールチップをフォーマットできます。
- B. 境界線を追加できます。
- C. 視覚化スケールを変更できます。
- D. データ ラベルをフォーマットできます。
- E. 色を変更できます。
正解:B
解説:
The Visualization Editor in Databricks SQL allows users to create and customize various types of charts and visualizations from the query results. Users can change the visualization type, select the data fields, adjust the colors, format the data labels, and modify the tooltips. However, there is no option to add borders to the visualizations in the Visualization Editor. Borders are not a supported feature of the new chart visualizations in Databricks1. Therefore, the statement that borders can be added is incorrect. Reference:
New chart visualizations in Databricks | Databricks on AWS
質問 # 49
ステークホルダーからデータアナリストに、50行のCSVファイル形式のルックアップデータセットが提供されました。データアナリストは、このデータセットをアップロードしてDatabricks SQLのテーブルとして使用する必要があります。
データ アナリストは、Databricks SOL で使用するためにファイルをテーブルにすばやくアップロードするには、どのアプローチを使用する必要がありますか?
- A. Databricks SQL 内の [作成] ページを使用してファイルをアップロードしてテーブルを作成します。
- B. データ値を手動でコピーしてクラウド ストレージに貼り付け、そのデータを Databricks にインポートしてテーブルを作成します。
- C. Partner Connect によって実現される Databricks とデスクトップ間の接続を介してテーブルを作成します。
- D. ファイルをクラウド ストレージにアップロードし、データを Databricks にインポートしてテーブルを作成します。
正解:A
解説:
Databricks provides a user-friendly interface that allows data analysts to quickly upload small datasets, such as a 50-row CSV file, and create tables within Databricks SQL. The steps are as follows:
Access the Data Upload Interface:
In the Databricks workspace, navigate to the sidebar and click on New > Add or upload data.
Select Create or modify a table.
Upload the CSV File:
Click on the browse button or drag and drop the CSV file directly onto the designated area.
The interface supports uploading up to 10 files simultaneously, with a total size limit of 2 GB.
Configure Table Settings:
After uploading, a preview of the data is displayed.
Specify the table name, select the appropriate schema, and configure any additional settings as needed.
Create the Table:
Once all configurations are set, click on the Create Table button to finalize the process.
This method is efficient for quickly importing small datasets without the need for additional tools or complex configurations. Options B, C, and D involve more complex or manual processes that are unnecessary for this task.
質問 # 50
データ アナリストが高階関数を使用する必要があるのは次のどの状況ですか。
- A. 組み込み関数をCatalyst Optimizerで実行する必要がある場合
- B. 単純なネストされていないデータにカスタムロジックを適用する必要がある場合
- C. 組み込み関数がタスクの実行に時間がかかりすぎる場合
- D. 配列データオブジェクトにカスタムロジックを大規模に適用する必要がある場合
- E. カスタムロジックをPythonネイティブコードに変換する必要がある場合
正解:D
解説:
Higher-order functions are a simple extension to SQL to manipulate nested data such as arrays. A higher-order function takes an array, implements how the array is processed, and what the result of the computation will be. It delegates to a lambda function how to process each item in the array. This allows you to define functions that manipulate arrays in SQL, without having to unpack and repack them, use UDFs, or rely on limited built-in functions. Higher-order functions provide a performance benefit over user defined functions. Reference: Higher-order functions | Databricks on AWS, Working with Nested Data Using Higher Order Functions in SQL on Databricks | Databricks Blog, Higher-order functions - Azure Databricks | Microsoft Learn, Optimization recommendations on Databricks | Databricks on AWS
質問 # 51
......
究極のガイドDatabricks-Certified-Data-Analyst-Associate日本語認証試験準備Data Analyst:https://jp.fast2test.com/Databricks-Certified-Data-Analyst-Associate-JPN-premium-file.html