

[2024年07月] を試そう!リアルProfessional-Data-Engineer問題集で100%無料Professional-Data-Engineer試験問題集
Professional-Data-EngineerのPDF問題集試験問題 有効なProfessional-Data-Engineer問題集
Google Professional-Data-Engineer認定試験は、データエンジニアリングに関連するさまざまな分野における候補者のスキルと知識を評価するために設計されています。この試験は、データ処理アーキテクチャ、データモデリング、データ取り込み、データ変換、およびデータストレージなどのトピックをカバーしています。候補者は、BigQuery、Cloud Storage、およびDataflowを含むGoogle Cloudテクノロジーについても強い理解を持っていることが期待されています。
Google Professional-Data-Engineer認定試験は、Google Cloudプラットフォームでデータ処理システムの設計、構築、管理に関する専門知識を実証しようとする専門家向けに設計されています。この試験は、ビッグデータソリューションを扱うデータエンジニア、データアーキテクト、およびデータアナリストを対象としています。この認定は、データ処理システムの設計と構築に必要なスキルと知識を検証し、生産環境でそれらを管理および監視します。
Google Professional-Data-Engineer認定試験は、データエンジニアリングに関連するさまざまな分野での候補者の能力を測定する困難なテストです。この試験は、データ処理、データストレージ、データ分析、データの視覚化、機械学習などのトピックをカバーする複数選択の質問で構成されています。この試験には、候補者がGoogleクラウドプラットフォームツールとサービスを使用して実際のデータエンジニアリングの問題を解決する能力を実証する必要がある実践的なタスクも含まれています。
質問 # 196
You want to process payment transactions in a point-of-sale application that will run on Google Cloud Platform. Your user base could grow exponentially, but you do not want to manage infrastructure scaling.
Which Google database service should you use?
- A. Cloud Bigtable
- B. BigQuery
- C. Cloud SQL
- D. Cloud Datastore
正解:D
解説:
https://cloud.google.com/datastore/docs/concepts/overview
質問 # 197
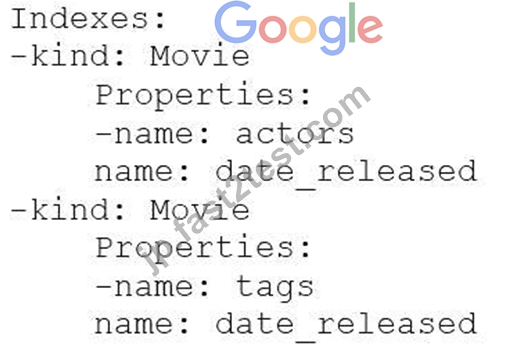
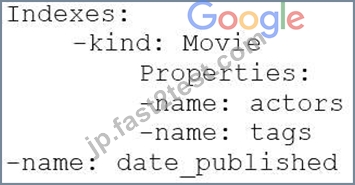
You are deploying a new storage system for your mobile application, which is a media streaming service. You decide the best fit is Google Cloud Datastore. You have entities with multiple properties, some of which can take on multiple values. For example, in the entity 'Movie' the property 'actors' and the property 'tags' have multiple values but the property 'date released' does not. A typical query would ask for all movies with actor=<actorname> ordered by date_released or all movies with tag=Comedy ordered by date_released. How should you avoid a combinatorial explosion in the number of indexes?
- A. Manually configure the index in your index config as follows:
- B. Set the following in your entity options: exclude_from_indexes = 'actors, tags'
- C. Set the following in your entity options: exclude_from_indexes = 'date_published'
- D. Manually configure the index in your index config as follows:
正解:A
質問 # 198
You need to deploy additional dependencies to all of a Cloud Dataproc cluster at startup using an existing initialization action. Company security policies require that Cloud Dataproc nodes do not have access to the Internet so public initialization actions cannot fetch resources. What should you do?
- A. Deploy the Cloud SQL Proxy on the Cloud Dataproc master
- B. Use an SSH tunnel to give the Cloud Dataproc cluster access to the Internet
- C. Use Resource Manager to add the service account used by the Cloud Dataproc cluster to the Network User role
- D. Copy all dependencies to a Cloud Storage bucket within your VPC security perimeter
正解:C
質問 # 199
Your company is performing data preprocessing for a learning algorithm in Google Cloud Dataflow.
Numerous data logs are being are being generated during this step, and the team wants to analyze them.
Due to the dynamic nature of the campaign, the data is growing exponentially every hour.
The data scientists have written the following code to read the data for a new key features in the logs.
BigQueryIO.Read
.named("ReadLogData")
.from("clouddataflow-readonly:samples.log_data")
You want to improve the performance of this data read. What should you do?
- A. Use of both the Google BigQuery TableSchemaand TableFieldSchemaclasses.
- B. Specify the TableReferenceobject in the code.
- C. Call a transform that returns TableRowobjects, where each element in the PCollectionrepresents
a single row in the table. - D. Use .fromQueryoperation to read specific fields from the table.
正解:C
質問 # 200
Your neural network model is taking days to train. You want to increase the training speed. What can you do?
- A. Increase the number of input features to your model.
- B. Increase the number of layers in your neural network.
- C. Subsample your test dataset.
- D. Subsample your training dataset.
正解:B
解説:
Explanation/Reference: https://towardsdatascience.com/how-to-increase-the-accuracy-of-a-neural-network-9f5d1c6f407d
質問 # 201
You work for a large fast food restaurant chain with over 400,000 employees. You store employee information in Google BigQuery in a Users table consisting of a FirstName field and a LastName field. A member of IT is building an application and asks you to modify the schema and data in BigQuery so the application can query a FullName field consisting of the value of the FirstName field concatenated with a space, followed by the value of the LastName field for each employee. How can you make that data available while minimizing cost?
- A. Create a Google Cloud Dataflow job that queries BigQuery for the entire Users table, concatenates the FirstName value and LastName value for each user, and loads the proper values for FirstName, LastName, and FullName into a new table in BigQuery.
- B. Use BigQuery to export the data for the table to a CSV file. Create a Google Cloud Dataproc job to process the CSV file and output a new CSV file containing the proper values for FirstName, LastName and FullName. Run a BigQuery load job to load the new CSV file into BigQuery.
- C. Create a view in BigQuery that concatenates the FirstName and LastName field values to produce the FullName.
- D. Add a new column called FullName to the Users table. Run an UPDATE statement that updates the FullName column for each user with the concatenation of the FirstName and LastName values.
正解:B
解説:
Import and Export to Bigquery from Cloud Storage is FREE. Also, when u store the csv files, Cloud Storage is cheaper than Bigquery. For processing Dataproc is cheaper than Dataflow.
質問 # 202
You are designing the database schema for a machine learning-based food ordering service that will
predict what users want to eat. Here is some of the information you need to store:
The user profile: What the user likes and doesn't like to eat
The user account information: Name, address, preferred meal times
The order information: When orders are made, from where, to whom
The database will be used to store all the transactional data of the product. You want to optimize the data
schema. Which Google Cloud Platform product should you use?
- A. Cloud Bigtable
- B. Cloud Datastore
- C. Cloud SQL
- D. BigQuery
正解:D
質問 # 203
How would you query specific partitions in a BigQuery table?
- A. Use the EXTRACT(DAY) clause
- B. Use DATE BETWEEN in the WHERE clause
- C. Use the __PARTITIONTIME pseudo-column in the WHERE clause
- D. Use the DAY column in the WHERE clause
正解:C
解説:
Partitioned tables include a pseudo column named _PARTITIONTIME that contains a date- based timestamp for data loaded into the table. To limit a query to particular partitions (such as Jan 1st and 2nd of 2017), use a clause similar to this:
WHERE _PARTITIONTIME BETWEEN TIMESTAMP('2017-01-01') AND
TIMESTAMP('2017-01-02')
Reference: https://cloud.google.com/bigquery/docs/partitioned-
tables#the_partitiontime_pseudo_column
質問 # 204
You want to migrate an on-premises Hadoop system to Cloud Dataproc. Hive is the primary tool in use, and the data format is Optimized Row Columnar (ORC). All ORC files have been successfully copied to a Cloud Storage bucket. You need to replicate some data to the cluster's local Hadoop Distributed File System (HDFS) to maximize performance. What are two ways to start using Hive in Cloud Dataproc?
(Choose two.)
- A. Run the gsutil utility to transfer all ORC files from the Cloud Storage bucket to any node of the Dataproc cluster. Mount the Hive tables locally.
- B. Leverage Cloud Storage connector for Hadoop to mount the ORC files as external Hive tables.
Replicate external Hive tables to the native ones. - C. Load the ORC files into BigQuery. Leverage BigQuery connector for Hadoop to mount the BigQuery tables as external Hive tables. Replicate external Hive tables to the native ones.
- D. Run the gsutil utility to transfer all ORC files from the Cloud Storage bucket to HDFS. Mount the Hive tables locally.
- E. Run the gsutil utility to transfer all ORC files from the Cloud Storage bucket to the master node of the Dataproc cluster. Then run the Hadoop utility to copy them do HDFS. Mount the Hive tables from HDFS.
正解:A、E
解説:
HDFS lies on datanode, data on masternode needs to be copied on datanode.
質問 # 205
Your company is in a highly regulated industry. One of your requirements is to ensure individual users have access only to the minimum amount of information required to do their jobs. You want to enforce this requirement with Google BigQuery.
Which three approaches can you take? (Choose three.)
- A. Segregate data across multiple tables or databases.
- B. Restrict BigQuery API access to approved users.
- C. Use Google Stackdriver Audit Logging to determine policy violations.
- D. Restrict access to tables by role.
- E. Ensure that the data is encrypted at all times.
- F. Disable writes to certain tables.
正解:B、C、D
解説:
bigquery.tables.create Create new tables.
bigquery.tables.delete Delete tables.
bigquery.tables.export Export table data out of BigQuery.
bigquery.tables.get Get table metadata.
To get table data, you need bigquery.tables.getData.
bigquery.tables.getData Get table data. This permission is required for querying table data.
To get table metadata, you need bigquery.tables.get.
bigquery.tables.list List tables and metadata on tables.
bigquery.tables.setCategory Set policy tags in table schema.
bigquery.tables.update
Update table metadata.
To update table data, you need bigquery.tables.updateData.
bigquery.tables.updateData
Update table data.
To update table metadata, you need bigquery.tables.update.
質問 # 206
What are all of the BigQuery operations that Google charges for?
- A. Storage, queries, and loading data from a file
- B. Storage, queries, and streaming inserts
- C. Queries and streaming inserts
- D. Storage, queries, and exporting data
正解:B
解説:
Google charges for storage, queries, and streaming inserts. Loading data from a file and exporting data are free operations.
Reference: https://cloud.google.com/bigquery/pricing
質問 # 207
Dataproc clusters contain many configuration files. To update these files, you will need to use the --properties option. The format for the option is: file_prefix:property=_____.
- A. id
- B. null
- C. details
- D. value
正解:D
解説:
To make updating files and properties easy, the --properties command uses a special format to specify the configuration file and the property and value within the file that should be updated. The formatting is as follows: file_prefix:property=value.
質問 # 208
You need to create a data pipeline that copies time-series transaction data so that it can be queried from within BigQuery by your data science team for analysis. Every hour, thousands of transactions are updated with a new status. The size of the intitial dataset is 1.5 PB, and it will grow by 3 TB per day. The data is heavily structured, and your data science team will build machine learning models based on this dat
a. You want to maximize performance and usability for your data science team. Which two strategies should you adopt? Choose 2 answers.
- A. Copy a daily snapshot of transaction data to Cloud Storage and store it as an Avro file. Use BigQuery's support for external data sources to query.
- B. Denormalize the data as must as possible.
- C. Preserve the structure of the data as much as possible.
- D. Use BigQuery UPDATE to further reduce the size of the dataset.
- E. Develop a data pipeline where status updates are appended to BigQuery instead of updated.
正解:A、B
質問 # 209
You work for a mid-sized enterprise that needs to move its operational system transaction data from an on-premises database to GCP. The database is about 20 TB in size. Which database should you choose?
- A. Cloud Spanner
- B. Cloud Bigtable
- C. Cloud Datastore
- D. Cloud SQL
正解:D
質問 # 210
You decided to use Cloud Datastore to ingest vehicle telemetry data in real time. You want to build a storage system that will account for the long-term data growth, while keeping the costs low. You also want to create snapshots of the data periodically, so that you can make a point-in-time (PIT) recovery, or clone a copy of the data for Cloud Datastore in a different environment. You want to archive these snapshots for a long time. Which two methods can accomplish this? (Choose two.)
- A. Write an application that uses Cloud Datastore client libraries to read all the entities. Treat each entity as a BigQuery table row via BigQuery streaming insert. Assign an export timestamp for each export, and attach it as an extra column for each row. Make sure that the BigQuery table is partitioned using the export timestamp column.
- B. Use managed export, and store the data in a Cloud Storage bucket using Nearline or Coldline class.
- C. Write an application that uses Cloud Datastore client libraries to read all the entities. Format the exported data into a JSON file. Apply compression before storing the data in Cloud Source Repositories.
- D. Use managed export, and then import the data into a BigQuery table created just for that export, and delete temporary export files.
- E. Use managed export, and then import to Cloud Datastore in a separate project under a unique namespace reserved for that export.
正解:C、D
質問 # 211
Your company built a TensorFlow neural-network model with a large number of neurons and layers. The model fits well for the training data. However, when tested against new data, it performs poorly.
What method can you employ to address this?
- A. Serialization
- B. Dimensionality Reduction
- C. Dropout Methods
- D. Threading
正解:C
解説:
https://medium.com/mlreview/a-simple-deep-learning-model-for-stock-price-prediction-using-tensorflow-30505541d877
質問 # 212
Which of these rules apply when you add preemptible workers to a Dataproc cluster (select 2 answers)?
- A. Preemptible workers cannot store data.
- B. Preemptible workers cannot use persistent disk.
- C. If a preemptible worker is reclaimed, then a replacement worker must be added manually.
- D. A Dataproc cluster cannot have only preemptible workers.
正解:A、D
解説:
Explanation
The following rules will apply when you use preemptible workers with a Cloud Dataproc cluster:
Processing only-Since preemptibles can be reclaimed at any time, preemptible workers do not store data.
Preemptibles added to a Cloud Dataproc cluster only function as processing nodes.
No preemptible-only clusters-To ensure clusters do not lose all workers, Cloud Dataproc cannot create preemptible-only clusters.
Persistent disk size-As a default, all preemptible workers are created with the smaller of 100GB or the primary worker boot disk size. This disk space is used for local caching of data and is not available through HDFS.
The managed group automatically re-adds workers lost due to reclamation as capacity permits.
Reference: https://cloud.google.com/dataproc/docs/concepts/preemptible-vms
質問 # 213
Your software uses a simple JSON format for all messages. These messages are published to Google Cloud Pub/Sub, then processed with Google Cloud Dataflow to create a real-time dashboard for the CFO.
During testing, you notice that some messages are missing in the dashboard. You check the logs, and all messages are being published to Cloud Pub/Sub successfully. What should you do next?
- A. Run a fixed dataset through the Cloud Dataflow pipeline and analyze the output.
- B. Use Google Stackdriver Monitoring on Cloud Pub/Sub to find the missing messages.
- C. Switch Cloud Dataflow to pull messages from Cloud Pub/Sub instead of Cloud Pub/Sub pushing messages to Cloud Dataflow.
- D. Check the dashboard application to see if it is not displaying correctly.
正解:A
質問 # 214
In order to securely transfer web traffic data from your computer's web browser to the Cloud Dataproc cluster you should use a(n) _____.
- A. VPN connection
- B. FTP connection
- C. Special browser
- D. SSH tunnel
正解:D
解説:
To connect to the web interfaces, it is recommended to use an SSH tunnel to create a secure connection to the master node.
Reference: https://cloud.google.com/dataproc/docs/concepts/cluster-web- interfaces#connecting_to_the_web_interfaces
質問 # 215
Your company built a TensorFlow neutral-network model with a large number of neurons and layers. The model fits well for the training data. However, when tested against new data, it performs poorly. What method can you employ to address this?
- A. Serialization
- B. Dimensionality Reduction
- C. Dropout Methods
- D. Threading
正解:C
質問 # 216
......
究極のProfessional-Data-Engineer無料準備ガイド最新のGoogle練習テスト問題集:https://jp.fast2test.com/Professional-Data-Engineer-premium-file.html
今すぐゲットせよ!高評価Google Professional-Data-Engineer試験問題集:https://drive.google.com/open?id=1pWc4snctqa8i5zBhmchAz6AhkSF5jbTu